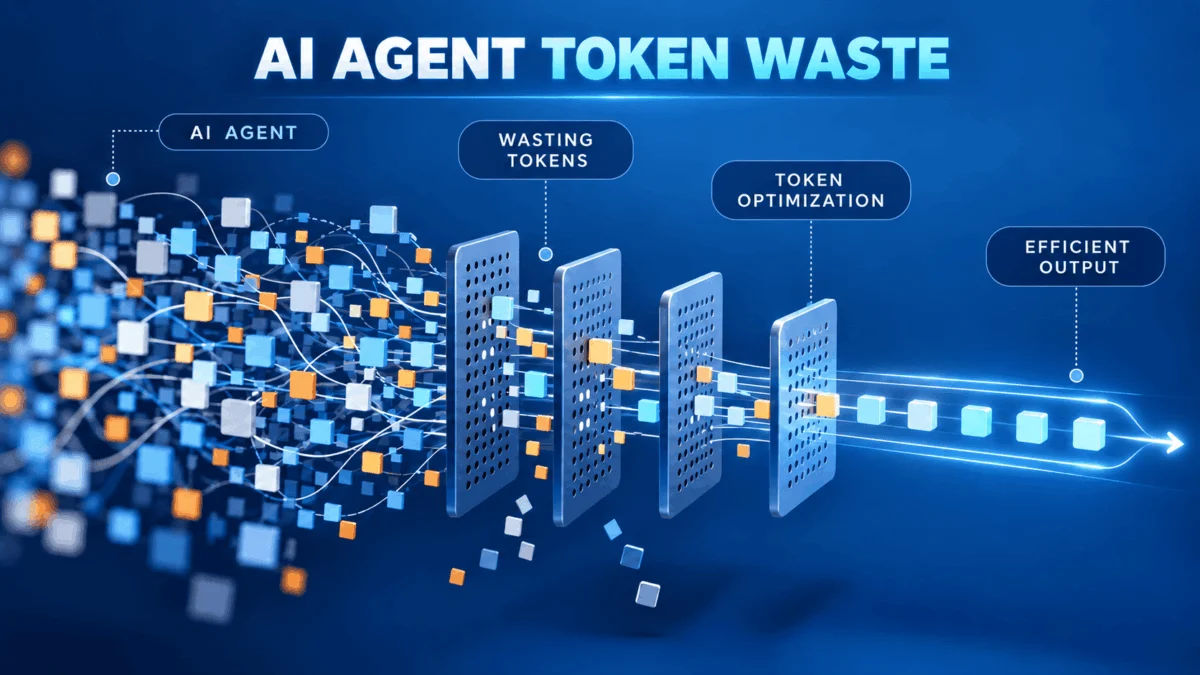
The rapid commercial adoption of autonomous artificial intelligence agents over the past twenty-four hours—and across the broader arc of the 2026 enterprise tech landscape—has introduced a harsh economic reality for software engineering teams. While prototyping an agentic workflow over a weekend has become trivial, keeping API billing under control by the third month of production operation has emerged as a major operational hurdle. Industry benchmarks indicate that naive agent architectures, which continuously append every user message, tool observation, and internal response to an endlessly expanding array, experience quadratically increasing inference latency alongside linearly inflating token costs. This systematic inefficiency stems fundamentally from treating the ephemeral context window as a permanent system of record.
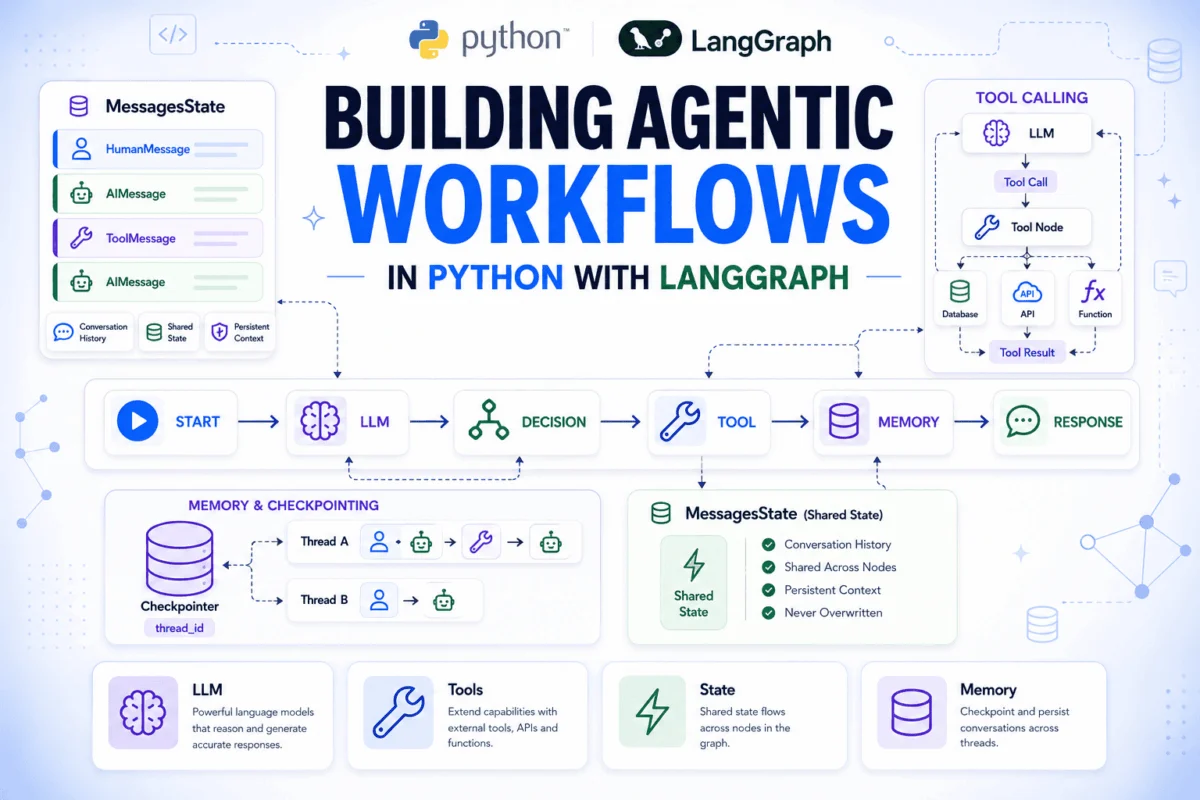
To understand the scope of the financial drain, enterprise architects must distinguish between context and state. Context represents the fleeting token payload transmitted over the wire with each individual request, whereas state is the durable, serialized representation of an agent’s true progress. Conflating these two concepts forces organizations to pay database-read prices on every single inference cycle. Technical analyses of production deployments reveal seven primary token-waste patterns that compromise system stability and inflate cloud infrastructure budgets, accompanied by the architectural interventions required to resolve them.
The Append-Only Trap: Context Window Accumulation
The most widespread architectural error in agent design is treating the prompt array as an append-only database. Every conversational turn, user query, tool observation, intermediate reasoning step, and assistant response is sequentially stacked into the prompt. By the twentieth turn, the agent is forced to re-read its entire operational history on every subsequent request, incurring quadratically increasing attention costs.
To mitigate this, engineering teams are implementing sliding context windows paired with semantic rolling summarization. Under this model, only the last N turns are passed verbatim, while older conversational turns are compressed into a dense background summary. Structural agent data is simultaneously offloaded to deterministic data stores such as SQLite or Redis rather than being reinjected into the prompt. However, this approach introduces distinct operational risks. Because summarization is inherently lossy, agents requiring exact uniform resource identifiers (URIs), cryptographic hashes, or code snippets from early sessions may experience hallucinations. Consequently, high-performance systems pair sliding windows with strict key-value lookup tools designed to retrieve exact strings when precision is paramount.
Uncompressed Tool Result Ingestion and Middleware Transformation
When an agent interacts with external third-party application programming interfaces—such as Stripe webhooks or verbose AWS cloud logs—it frequently receives deeply nested JSON payloads engineered specifically for machine consumption rather than language model reasoning. Injecting these raw responses directly into the observation context consumes thousands of tokens containing non-essential data.
Modern engineering practices introduce a dedicated middleware transformation layer positioned directly between tool execution and context injection. This layer strips null values, filters non-essential keys, and restructures complex JSON hierarchies into dense YAML or structured Markdown formats. Furthermore, deterministic pre-processing passes strip redundant timestamps, thread IDs, and boilerplate code before the model processes the payload. Despite these efficiency gains, aggressive filtering can inadvertently strip vital metadata, such as pagination cursors. If an agent requires pagination through extensive result sets, the accidental removal of a next_token field will silently fracture the retrieval loop.
Retrieval Thrash and the Grep-and-Dump Anti-Pattern
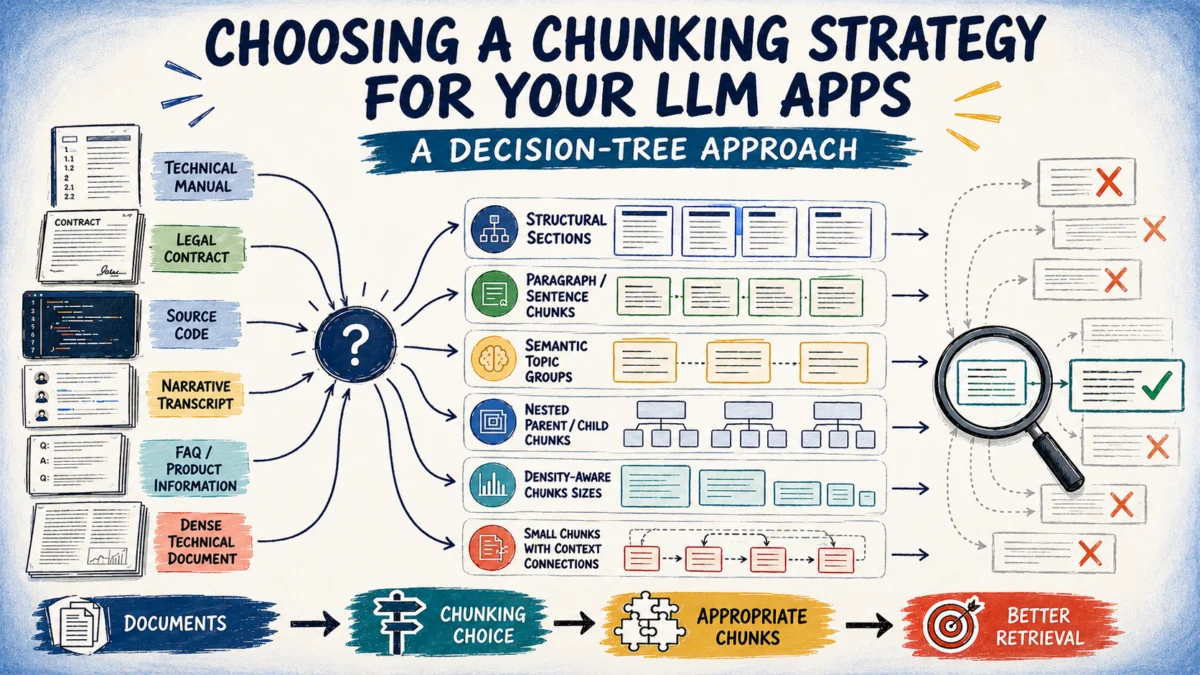
In code-generation agents and retrieval-augmented generation (RAG) systems, developers frequently rely on naive text matching to locate content, subsequently dumping entire files into the context window. When an agent requires a single targeted function, the orchestrator retrieves the entire multi-thousand-line source file, effectively reading an entire volume to answer a single query.
The architectural remedy involves shifting toward chunked, Abstract Syntax Tree (AST)-aware retrieval. By parsing code into a live call graph during the indexing phase, orchestrators can query the index to return only the exact function signature, its corresponding docstring, and immediate structural dependencies. Tools utilizing parsers like Tree-sitter can reduce payload sizes from thousands of tokens down to a few hundred. Nevertheless, graph-aware retrieval mandates continuous, asynchronous indexing pipelines. If the vector index drifts behind the main software branch, the agent will reason against stale state, attempt to invoke deprecated functions, and burn valuable output tokens debugging resultant errors.
Static Tool Schema Bloat and Finite State Routing
Agent frameworks frequently define tool schemas globally, injecting the entire registry into every language model call. While harmless for small toolsets, agents managing thirty to fifty tools force the model to read thousands of tokens of schema definitions per request, even when the vast majority of tools remain entirely irrelevant to the current task phase.
To counter schema bloat, advanced architectures employ context-aware tool pruning governed by a finite state machine. The operational state of the agent dynamically dictates which tools are exposed. For instance, an agent in a discovery state receives exclusively search and read tools, while an execution state restricts access to mutation and write utilities. However, dynamic tool schemas directly interfere with prompt caching mechanisms. Whenever the tool subset array shifts, the underlying LLM provider must recompute the Key-Value (KV) cache for the affected prompt prefix, resulting in elevated latency and forfeiture of cache-hit cost discounts.
Unbounded Chain-of-Thought Loops and Circuit Breakers
Autonomous agents operating in production environments are acutely vulnerable to execution loops. When a tool call fails, the agent attempts a retry; if the underlying failure persists, the agent continues generating reasoning loops and retry attempts indefinitely. Without enforced boundaries, a single stalled task can consume tens of thousands of expensive output tokens.
Production systems mitigate this risk by implementing orchestrator-level circuit breakers. These mechanisms enforce strict maximum retry thresholds on tool failures and establish absolute output token budgets per action. When thresholds are reached, the orchestrator intercepts the loop, initiates a deterministic fallback, or escalates the task to human operators. While this protects against runaway billing, overly aggressive circuit breakers can produce false positives on genuinely complex, multi-step planning tasks that require extensive search cycles before reaching synthesis.
Neglecting KV Cache Optimization and Prompt Prefixing
Large language model providers cache the key-value representations of prompt prefixes to bypass redundant attention computations over previously processed content. Many agent deployments inadvertently neutralize this capability by injecting dynamic variables—such as timestamps, unique user identifiers, or short-term memory snapshots—at the very top of the prompt structure before the static content.
Optimized architectures enforce a strict static-to-dynamic gradient. Massive static assets, including system prompts, organizational guidelines, and persistent schemas, are positioned at the absolute apex of the request payload, shielding them from dynamic interference. Despite these optimizations, provider-specific Time-To-Live (TTL) constraints—typically ranging from five to fifteen minutes—mean that low-traffic systems or slow reasoning cycles will experience cache expiration, forcing organizations to pay full price for prompt prefixes regardless of structural layout.
Monolithic Routing and Model Tiering
A pervasive economic inefficiency in enterprise AI deployments involves utilizing premium frontier models—such as Opus-tier or GPT-4-class architectures—for routine tasks like parsing basic JSON, classifying user intent, or summarizing application logs. This practice parallels employing senior enterprise architects for administrative data entry.
Cascaded LLM routing resolves this by deploying smaller, high-speed models—such as Haiku-tier or Gemini Flash-class variants—for structural data extraction, intent classification, and log summarization. Requests are routed to frontier models exclusively when multi-step reasoning is explicitly required. While open-source frameworks like LiteLLM simplify provider-agnostic routing, improper configuration can introduce significant failure surfaces; if a lightweight classification layer misroutes a complex request due to insufficient reasoning capacity, it passes erroneous parameters to the frontier model, effectively doubling token expenditures for that transaction.
Broader Implications for Enterprise AI Maturity
As artificial intelligence systems approach their hundredth day in production environments, token optimization transitions from a rudimentary cost-management exercise into a fundamental data quality imperative. Unchecked token consumption directly correlates with degraded inference latency, expanded attack surfaces for hallucinations, and accelerated accumulation of stale operational data within vector stores and episodic memory banks.
Industry analysts emphasize that architectural decisions made during initial software development compound exponentially over time. Balancing the tensions between dynamic tool pruning, prompt caching, and tiered model routing requires rigorous empirical analysis of real production traces rather than speculative design. Ultimately, constraining agent context windows to the strict minimum required for task execution enforces predictable operational behavior, minimizes orchestrator timeouts, and establishes a stable foundation for scalable enterprise artificial intelligence deployments.