
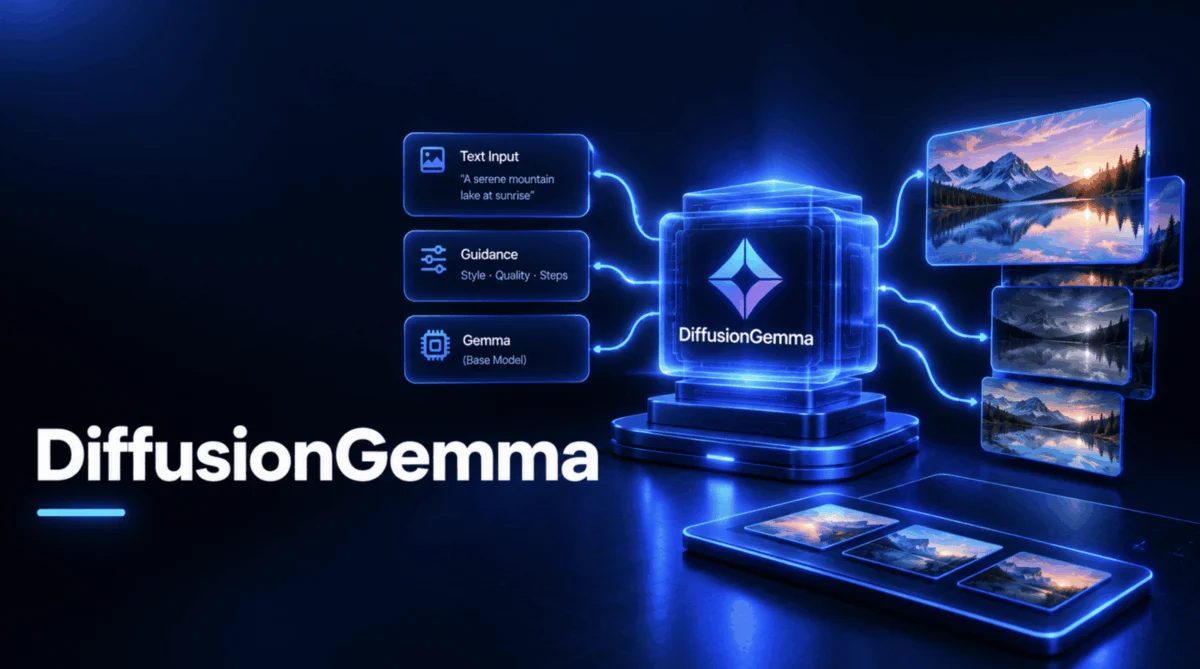
Google DeepMind has officially released DiffusionGemma, an experimental open-source AI model that challenges the foundational mechanics of modern text generation. Launched on June 10, 2026, the model discards the traditional left-to-right, autoregressive framework utilized by nearly all major language models—including GPT, Claude, and standard Gemma variants—in favor of a parallel, diffusion-based text generation process. By adapting the iterative denoising techniques traditionally reserved for image generators like Stable Diffusion, Google DeepMind’s latest offering introduces capabilities previously unseen in text architecture, such as dynamic self-correction and compute-bound workload optimization.
The release arrives at a critical juncture for artificial intelligence hardware and deployment. While traditional autoregressive architectures have scaled successfully across massive cloud environments, they face severe operational bottlenecks on edge devices and local consumer hardware due to memory bandwidth constraints. DiffusionGemma attempts to circumvent these hardware limitations by shifting the primary computational load from sequential memory fetching to parallelized matrix processing. Licensed under the permissive Apache 2.0 framework, the experimental model is immediately available to the developer community for research, benchmarking, and local deployment.
Background Context and Technological Evolution
The prevailing paradigm in natural language processing relies on autoregressive decoding. Under this system, models produce text sequentially, predicting one token at a time while conditioning each new word on the entirety of the preceding sequence. Although this approach has driven the generative AI boom, it creates a fundamental structural vulnerability: once a token is committed to the context window, it is permanent. If an autoregressive model diverges or hallucinates early in a complex response, it lacks the architectural capacity to backtrack or revise its output organically, often compounding errors as the sequence lengthens.
Furthermore, sequential generation creates a severe hardware paradox. When running large language models locally on consumer hardware—such as an NVIDIA RTX 4090 or high-end workstation GPUs—the primary performance barrier is not the raw floating-point compute capacity of the graphics card, but rather the memory bandwidth required to fetch model weights from VRAM for every single token produced. Consequently, the GPU’s advanced compute cores remain largely underutilized while waiting for data movement.
Google DeepMind’s DiffusionGemma resolves this bottleneck by reimagining how text is synthesized. Rather than writing a sentence sequentially, the model initiates generation by populating a canvas with a predefined block of 256 placeholder tokens, which resemble random noise. Through a process designated as Uniform State Diffusion, the system denoises the entire block simultaneously across multiple iterative passes. Tokens carrying high statistical confidence assist in resolving neighboring tokens of lower certainty, allowing the entire sequence to converge progressively into coherent language.
Architecture, Parameters, and Multimodal Capabilities
Under the hood, DiffusionGemma is constructed upon the structural foundation of the Gemma 4 26B model family. It utilizes an advanced Mixture-of-Experts (MoE) architecture, boasting a total of 26 billion parameters while activating only 3.8 billion parameters per token. This design choice, reflected in its official identifier "google/diffusiongemma-26B-A4B-it," ensures high-capacity representation without demanding excessive active compute during inference cycles.
When properly quantized, the model operates within an 18GB VRAM footprint. This memory efficiency brings advanced experimental architecture within reach of single-GPU consumer setups, though unquantized deployments on enterprise infrastructure such as NVIDIA A100 or H100 arrays remain recommended for unconstrained research workflows.
On the input side, DiffusionGemma functions as a multimodal system. It natively processes text, high-resolution images featuring variable aspect ratios, and video inputs. However, audio modalities are currently unsupported. Despite its broad input capabilities, the model strictly outputs text. Unlike theoretical image-to-text or diffusion-to-multimodal frameworks, DiffusionGemma applies its diffusion mechanics exclusively to the text generation phase, while relying on standard transformer encoders for incoming visual data.
Block-Autoregressive Denoising and Self-Correction
To manage outputs that extend beyond the initial 256-token canvas, DiffusionGemma implements a methodology known as block-autoregressive denoising. Once an active 256-token block achieves convergence, it is committed to the model’s Key-Value (KV) cache via conventional causal attention mechanisms. A fresh, empty canvas is then initialized, denoising new text while conditioning on the historical context established by all previously committed blocks.
This hybrid approach preserves long-form text stability through causal history tracking while leveraging bidirectional attention within each active canvas block. Within an active canvas, any token can attend to any other token simultaneously. This bidirectional awareness unlocks a transformative capability: dynamic self-correction. If the model’s internal confidence regarding a specific token drops midway through the denoising passes, the sampler can re-noise the token and allow the network to recalculate its prediction. In traditional autoregressive models, such mid-stream correction is structurally impossible.
Implementation, Setup, and Software Requirements
Deploying DiffusionGemma requires specific software environments due to its novel underlying architecture. Because standard transformer classes cannot interpret block-diffusion loops, the model relies on dedicated framework classes introduced in Hugging Face Transformers version 5.11.0 and later.
Developers can initialize the environment using standard Python package management:
pip install torch accelerate
pip install "transformers>=5.11.0"
Loading the model requires the dedicated DiffusionGemmaForBlockDiffusion class rather than standard causal language modeling wrappers. Below is the standard implementation for loading the model and processor:
from transformers import DiffusionGemmaForBlockDiffusion, AutoProcessor

MODEL_ID = "google/diffusiongemma-26B-A4B-it"

model = DiffusionGemmaForBlockDiffusion.from_pretrained(
    MODEL_ID, dtype="auto", device_map="auto",
)
processor = AutoProcessor.from_pretrained(MODEL_ID)
By leveraging dtype="auto" and device_map="auto", the Hugging Face library automatically optimizes precision based on available hardware and distributes tensor weights efficiently across available GPUs. The AutoProcessor handles multimodal tokenization, translating complex prompt structures containing both imagery and text into the internal token representations required by the model.
Real-Time Monitoring and Advanced Generation Features
One of the most notable aspects of DiffusionGemma is the transparency it offers during the generation phase. Through the inclusion of the TextDiffusionStreamer utility, developers can inspect the iterative refinement of the text canvas in real time, observing how random noise transitions into structured prose across multiple denoising steps.
Furthermore, the model incorporates advanced steering mechanisms, including native support for system instructions and a configurable thinking mode. By passing enable_thinking=True through the chat template processor, users instruct the model to execute a multi-step reasoning protocol within an isolated internal thought channel prior to generating the final user-facing output.
message = ["role": "user", "content": "What is the chemical formula for water?"]

input_ids = processor.apply_chat_template(
    message, tokenize=True, add_generation_prompt=True,
    return_dict=True, return_tensors="pt", enable_thinking=True,
).to(model.device)

output = model.generate(**input_ids, max_new_tokens=512)
print(processor.decode(output[0], skip_special_tokens=False))
Production Serving and Recommended Sampling Parameters
For enterprise environments and scaled deployments, Google DeepMind collaborated directly with the vLLM team to integrate DiffusionGemma’s iterative denoising loops into the vLLM serving engine. Production deployments utilize specialized command-line configurations to optimize throughput and manage entropy bounds during generation:
vllm serve google/diffusiongemma-26B-A4B-it
  --max-model-len 262144
  --max-num-seqs 4
  --gpu-memory-utilization 0.85
  --attention-backend TRITON_ATTN
  --generation-config vllm
  --hf-overrides '"diffusion_sampler": "entropy_bound", "diffusion_entropy_bound": 0.1'
  --diffusion-config '"canvas_length": 256'
  --enable-chunked-prefill
Google DeepMind has also published official parameter recommendations for controlling the diffusion sampling process. The framework utilizes a maximum denoising ceiling of 48 steps per canvas, though adaptive early-stopping mechanisms typically halt the loop within 12 to 16 steps once statistical confidence thresholds are met. A linear temperature schedule—initiating at 0.8 to encourage exploratory generation and dropping to 0.4 to lock in final token selections—mirrors the macroscopic transition from noise to clarity.
Broader Implications and Industry Outlook
The introduction of DiffusionGemma marks an important inflection point in foundational model research. Industry analysts note that while autoregressive models remain the undisputed champions for massive, high-concurrency cloud API services, parallel diffusion architectures offer a compelling alternative for local inference, edge computing, and privacy-focused local hardware installations.
By alleviating memory bandwidth bottlenecks and introducing genuine self-correction loops to text generation, Google DeepMind has opened a viable secondary research track for large language model development. As developers explore the Apache 2.0 model in local and production environments, the insights gathered from DiffusionGemma’s parallel denoising mechanics are expected to influence future iterations of generative AI architecture across the industry.