The Mechanics of Silent Communication
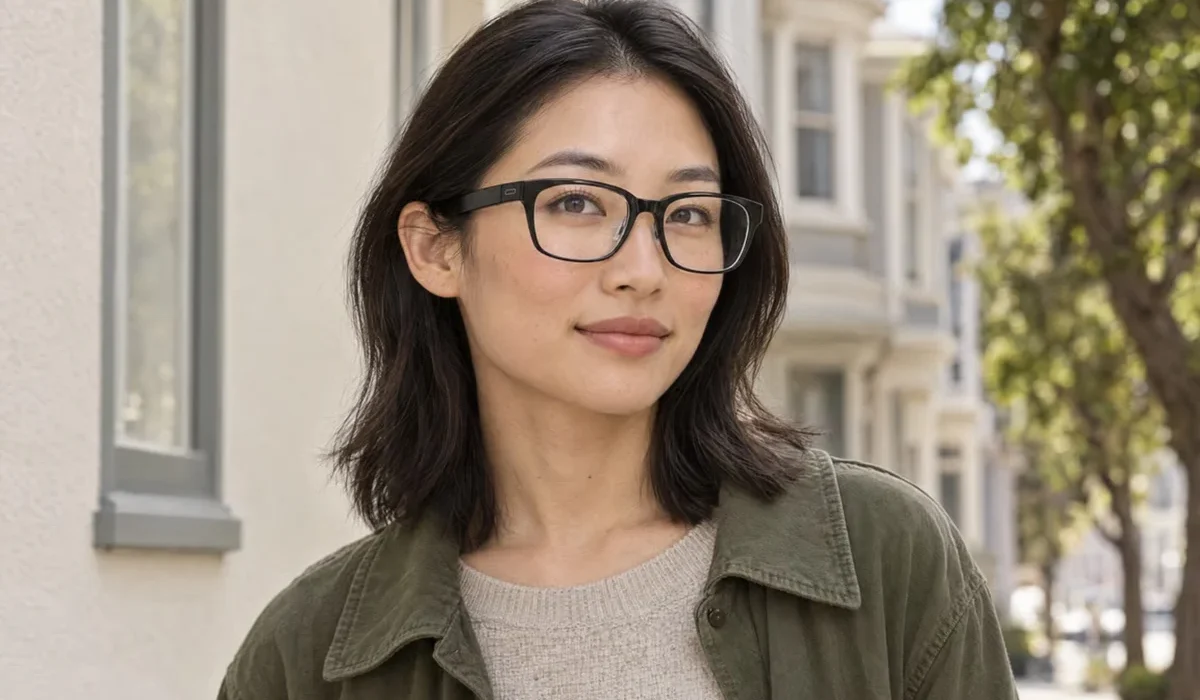
The technology underpinning the Subvocal smart glasses departs from traditional approaches to speech recognition. Unlike devices that rely on microphones to capture acoustic vibrations or cameras to perform complex lip-reading analysis—which often suffer from privacy concerns and accuracy issues in low-light environments—the Subvocal system utilizes radar-based sensors.
These sensors emit low-power radar signals directed at the user’s face. As the user forms words silently, the subtle muscular contractions and movements of the jaw, tongue, and cheeks alter the way these radar signals reflect back to the sensor array. A sophisticated artificial intelligence model then interprets these micro-variations in the radar return, translating the physical effort into high-fidelity text in real time. The company claims the device can achieve speeds exceeding 200 words per minute, a rate that rivals, and in some cases exceeds, professional-grade keyboard typing.

Crucially, the system does not require the user to be completely immobile. The user must intentionally mouth the words, ensuring that the intent behind the communication remains deliberate. This distinction is vital; it prevents the device from accidentally transcribing subconscious facial twitches or casual expressions, maintaining a level of user agency that is often lacking in more passive monitoring systems.
Background and Development Timeline
The genesis of The Subvocal Company lies in the broader industry movement toward "silent speech interfaces" (SSI). For years, researchers have experimented with electromyography (EMG) sensors—stickers placed on the throat or jaw—to detect electrical signals from speech muscles. However, these prototypes have struggled with portability and the social stigma of wearing adhesive electrodes.
Subvocal’s pivot toward integrated eyewear represents a maturation of the form factor. The project recently gained significant industry attention following a successful funding round of $1.3 million, backed by Y Combinator and Afore Capital. The involvement of Y Combinator, in particular, signals a belief that this technology has the potential to scale beyond academic research and into the consumer electronics market.

The following timeline illustrates the project’s progression:
- Early 2026: Development of the initial radar-based prototype.
- Mid-2026: Refinement of the AI model to handle diverse linguistic patterns and phonemes.
- October 2026: Public unveiling of the project, accompanied by a $1.3 million seed funding announcement and the opening of a pre-order waitlist in the United States.
- Q1 2027 (Projected): Commencement of commercial shipping for early adopters.
Market Implications and Social Dynamics
The potential for silent communication technology extends well beyond mere convenience. In a professional context, the implications for productivity are substantial. Employees who work in high-density office environments often struggle with the "noise pollution" of standard dictation software. By moving to a silent interface, a user could theoretically draft long-form reports or respond to emails in a public library or a quiet boardroom without disrupting colleagues.
Furthermore, there is a clear accessibility angle. For individuals with speech impairments or those who find traditional physical typing painful due to repetitive strain injuries (RSI) or other physical limitations, a silent speech-to-text interface could be transformative. If the technology performs as advertised, it could bridge the gap for users who currently rely on cumbersome hardware or slow, manual input methods.

However, the technology does not arrive without skepticism. Independent verification of the 200-word-per-minute claim is currently absent. Speech recognition software, even in its most advanced state, often struggles with regional accents, colloquialisms, and jargon. The effectiveness of the AI model in filtering out non-verbal movements—such as smiling, yawning, or chewing—remains a primary technical hurdle. The company has yet to release white papers detailing how the device differentiates between "speech-related movement" and "natural facial expression" in high-intensity, real-world scenarios.
Commercial Strategy and Accessibility
The Subvocal Company has adopted a direct-to-consumer model. The device is currently priced at $499, with a $199 deposit required to secure a reservation. This price point positions the glasses as a premium productivity tool, comparable to high-end tablets or enterprise-grade computer peripherals.
To address the practicalities of everyday wear, the company has confirmed that prescription lenses will be available for an additional cost. This is a critical step in ensuring adoption; if the glasses are to be used for extended periods throughout the workday, they must function as a replacement for, or an addition to, the user’s primary eyewear.

Critical Challenges and Future Outlook
As the company moves toward its Q1 2027 shipping window, it faces several significant hurdles. Beyond the technical challenges of speech-to-text accuracy, there is the issue of "device fatigue." Wearables that require constant, deliberate muscle movement—even at a micro level—may lead to user exhaustion over prolonged sessions.
Furthermore, privacy remains a paramount concern. While the company emphasizes that no cameras are used, the presence of radar sensors that map the user’s face and translate internal vocalizations is a new frontier for data privacy. Consumers will likely demand transparency regarding how this "motion data" is processed, stored, and encrypted. If the AI processing occurs on-device (Edge AI), it would alleviate many privacy fears, but the company has not yet confirmed the extent of its on-board compute capabilities versus cloud-based processing.
From a sociological perspective, the adoption of silent speech interfaces could fundamentally alter how we perceive digital communication in public. If we enter an era where people can "talk" to their devices without moving their lips in a way that is audible, the social friction of the last decade—where voice assistants like Siri or Alexa were often avoided in public to prevent embarrassment—may disappear entirely.

The industry will be watching closely as the first units reach consumers. If Subvocal succeeds, it will likely trigger a rush of competitors, potentially leading to a new category of "silent-input" wearables. If it fails to meet the lofty performance targets, it may serve as a cautionary tale about the limits of radar-based sensing in complex biological environments. For now, the prospect of writing an email by simply "mouthing" it remains one of the most compelling, if unproven, promises in the current tech landscape. As we approach the first quarter of 2027, the gap between the vision of a "keyboard-free future" and the reality of the technology will finally be put to the test.