



The architecture of modern machine learning pipelines is undergoing a fundamental transformation as practitioners increasingly integrate Large Language Models (LLMs) into traditional tabular and text classification workflows. A central debate in this paradigm shift involves choosing between locally hosted open-source models and high-performance cloud-accelerated inference engines. A comparative benchmark evaluating local zero-shot classification using Scikit-Ollama against cloud-accelerated inference via a Groq-backed Scikit-LLM pipeline provides vital empirical data on how these two deployment strategies stack up across key performance indicators: processing speed, classification accuracy, data privacy, and operational expenditures.
As organizations scale their natural language processing (NLP) applications, the friction between infrastructure overhead and API dependency has intensified. Traditional machine learning workflows have long relied on the scikit-learn API design pattern, characterized by straightforward fit and predict methods. Bridging the gap between generative AI capabilities and standard scikit-learn syntax allows developers to seamlessly swap underlying engines without rewriting core application logic. This standardization is precisely what libraries like Scikit-LLM and Scikit-Ollama aim to achieve, enabling direct head-to-head evaluations under identical testing frameworks.
Background Context and Technical Architecture
The integration of LLMs into scikit-learn pipelines represents a convergence of traditional predictive modeling and generative artificial intelligence. Scikit-LLM was developed to bridge the gap between OpenAI’s powerful API endpoints and the modular, pipeline-oriented structure of scikit-learn. By wrapping API calls into standard estimator classes, developers could leverage transformer-based intelligence within familiar grid search, cross-validation, and pipelining workflows. However, reliance on proprietary cloud services historically introduced variables such as latency, variable cloud costs, and strict rate limits.
Concurrently, the open-source movement championed by runtimes like Ollama has democratized local LLM execution. Ollama allows developers to download, manage, and execute models—such as Meta’s Llama 3—directly on consumer-grade hardware or cloud virtual machines without external network dependencies. Scikit-Ollama emerged to extend this local capability into the scikit-learn ecosystem, mirroring the functional utility of Scikit-LLM but routing all inference computations through a local server daemon.
To introduce a high-performance alternative to traditional cloud endpoints, developers frequently turn to specialized hardware accelerators like Groq’s Language Processing Units (LPUs). Groq’s deterministic architecture is engineered to optimize token generation speeds, drastically reducing latency compared to traditional GPU-based cloud hosting. By routing Scikit-LLM requests through Groq’s custom URL endpoints, practitioners can combine the familiar scikit-learn wrapper with extreme cloud inference speeds, often maintaining low or zero-tier pricing structures during promotional or development phases.
Environment Setup and Experimental Methodology
Designing a fair benchmark requires isolating the classification engine while keeping the dataset, evaluation metrics, and execution wrappers completely constant. The empirical evaluation utilizes a standardized Python testing script designed to run within modern data science environments, such as Google Colab or local Integrated Development Environments (IDEs).
The experimental setup begins with the installation of wrapper libraries and the configuration of respective runtime environments. For the local benchmark, the Ollama server is initialized programmatically as a background process, ensuring that the Llama 3 model is actively loaded into memory. Simultaneously, the cloud configuration leverages Scikit-LLM’s ability to override default API routing, directing requests to Groq’s infrastructure via custom URL parameters authenticated by secure environment variables.
To measure performance objectively, a universal helper function, benchmark_estimator, is implemented. This function wraps the standard scikit-learn lifecycle:
- It records the precise start time using high-resolution performance counters (
time.perf_counter()). - It executes the
.fit()method, supplying the candidate labels required for zero-shot text classification. - It calls the
.predict()method across a standardized validation corpus. - It measures total elapsed execution time and computes classification accuracy against ground-truth labels using Scikit-learn’s
accuracy_scoremetric.
Chronology of the Benchmark Scenarios
The empirical evaluation is divided into two distinct operational scenarios to observe the divergence in resource utilization and inference speed.
Scenario 1: Local Zero-Shot Classification with Scikit-Ollama
In the first phase of the evaluation, the pipeline instantiates a ZeroShotOllamaClassifier targeting the locally hosted Llama 3 model. The test corpus consists of representative customer feedback statements, categorized into binary sentiment classes ("Positive" and "Negative").
When executed on standard cloud-hosted CPU/GPU hybrid hardware instances without dedicated local acceleration, the local execution yields significant insights into resource constraints. The local model successfully processes the dataset, achieving an 80% accuracy score by correctly classifying four out of five test samples. However, the operational trade-off becomes immediately apparent in the execution timeline: the total elapsed time reaches 80.71 seconds.
While the direct financial cost remains strictly $0.00 due to local hardware execution, the latency penalty underscores the heavy computational load placed on local processors when running multi-billion parameter transformer models without specialized NPUs or high-end GPUs.
Scenario 2: Cloud-Backed Zero-Shot Classification with Scikit-LLM and Groq
The second phase shifts the computational burden to the cloud by initializing a ZeroShotGPTClassifier via Scikit-LLM, with traffic dynamically routed to Groq’s API infrastructure using custom endpoint configurations. Authentication is handled securely via cloud secret management systems, pulling the required API key without exposing credentials in the source code.
Using Groq’s hardware-accelerated LPU backend, the identical zero-shot classification task is executed against the test corpus. The results demonstrate a dramatic shift in performance metrics. The cloud-backed pipeline completes the evaluation in just 2.02 seconds—achieving a roughly 40-fold speedup compared to the local Ollama execution. Furthermore, the model achieves a 100% accuracy score on the test dataset, correctly predicting all five ground-truth labels. The cost remains $0.00 under the current free tier of the Groq API, though production-scale implementations would eventually factor in token-based pricing models.
Comparative Analysis of Findings
Analyzing the empirical data reveals clear operational trade-offs that guide enterprise decision-making when deploying LLM classifiers:
- Inference Speed and Latency: Cloud-accelerated pipelines powered by specialized inference hardware (such as Groq LPUs) drastically outperform local CPU/standard GPU setups in raw token generation and classification speed. For real-time applications requiring millisecond-level responses, cloud acceleration is virtually mandatory.
- Cost and Scalability: While local inference incurs zero marginal cost per API call, it demands significant upfront capital expenditure in hardware (such as high-end GPUs or Apple Silicon with unified memory) to achieve acceptable throughput. Conversely, cloud APIs offer elastic scalability but introduce ongoing operational expenditures and dependency on third-party uptime.
- Data Privacy and Compliance: Local inference via tools like Scikit-Ollama ensures that sensitive proprietary data never leaves the local perimeter, satisfying stringent regulatory frameworks such as GDPR, HIPAA, or financial data residency requirements. Cloud-backed solutions, even with enterprise privacy guarantees, inherently require transmitting data across external networks.
- Accuracy and Model Flexibility: Model accuracy heavily depends on the specific weights and architecture of the chosen LLM rather than the wrapper library itself. Both Scikit-LLM and Scikit-Ollama successfully abstract the underlying model, allowing developers to prioritize accuracy by selecting larger, more capable base models regardless of where they are hosted.
Broader Industry Implications and Future Outlook
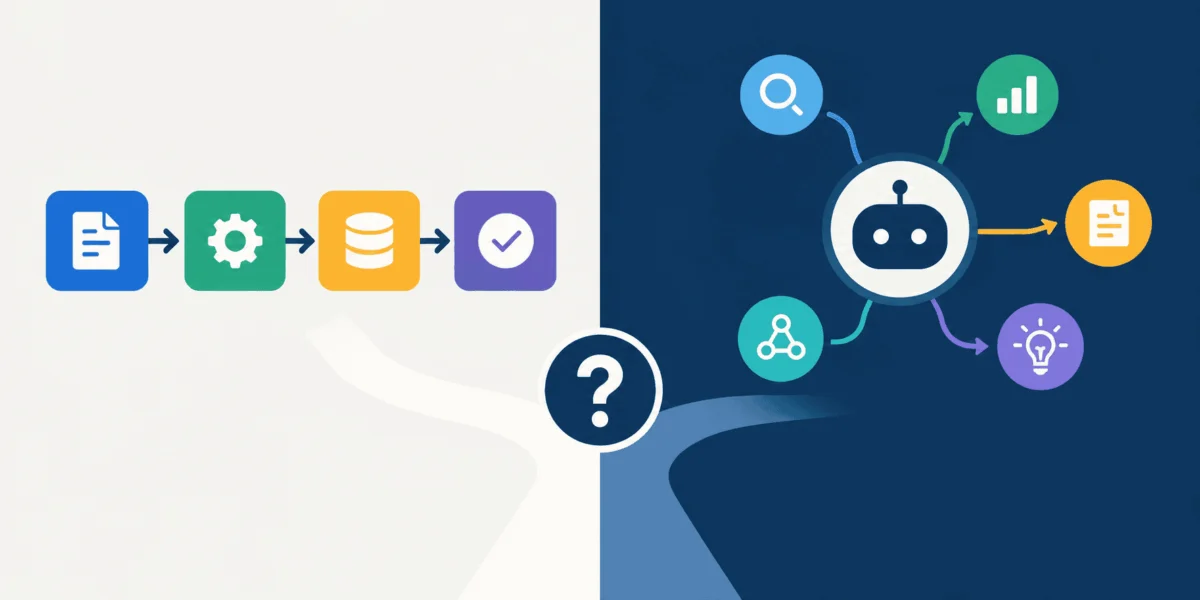
The convergence of Scikit-learn compatible wrappers with diverse inference backends marks a mature phase in machine learning engineering. Developers are no longer forced to choose between the robust, modular design patterns of traditional data science pipelines and the cutting-edge semantic capabilities of generative AI.
As enterprises increasingly demand hybrid deployment architectures, the ability to switch effortlessly between local open-source models and high-speed cloud providers using identical codebases will become a standard design pattern. Tools that minimize vendor lock-in while providing transparent benchmarking metrics empower engineering teams to dynamically optimize their pipelines based on shifting constraints—balancing the absolute data sovereignty of local hardware against the blistering speed and scale of cloud accelerators.