

The rapid evolution of open-weight large language models has traditionally centered on generative tasks, where systems output continuous streams of text token by token. However, a wide range of enterprise applications, such as customer service routing, automated content moderation, and real-time fraud detection, do not require discursive explanations. Instead, they demand rapid, deterministic decisions backed by statistical confidence scores. To address this architectural mismatch, developers and machine learning engineers are increasingly adopting specialized decision models—such as the emerging Jev, Laya, and Clef systems—which bypass text generation entirely to evaluate predefined options and yield explicit probability estimations.
Recent enhancements to the Unsloth framework have significantly lowered the technical and computational barriers to creating these specialized architectures. By introducing native support for decision model training from open-weight foundational families like Qwen and Gemma, developers can now optimize standard language models into hyper-efficient intent classifiers. This capability allows organizations to leverage pre-trained linguistic comprehension while enforcing strict output structures, optimizing inference latency, and eliminating the risks associated with hallucinatory text generation in mission-critical workflows.
Understanding the Mechanics of Decision Models
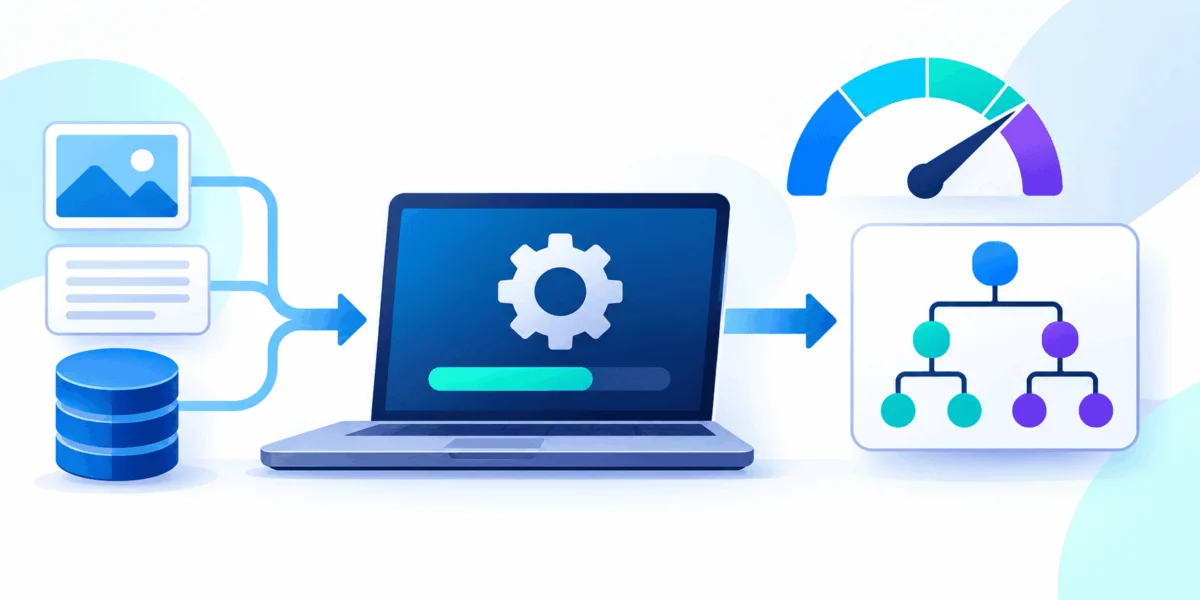
Traditional large language models operate on next-token prediction, consuming vast amounts of computational power to synthesize natural language answers even when a binary or categorical choice is required. For example, when a user submits a query regarding a banking account, a generative model will often generate paragraphs explaining banking procedures, security policies, and navigation menus. Conversely, a decision model evaluates the semantic weight of the input against a fixed set of criteria, instantly returning a structured payload containing the selected category and a statistical confidence score.
The technological foundation of this approach relies on specialized architectural heads attached to foundational backbones. Through Unsloth’s FastDecisionModel interface, developers can seamlessly append a decision head to pretrained models. This mechanism processes both the contextual input and the designated choices simultaneously, scoring potential answers without executing conventional text decoding loops. The framework inherently supports multiple classification paradigms, including binary decisions, numerical scoring, and discrete categorical selections, making it uniquely adaptable to complex natural language understanding requirements.
Experimental Setup and Infrastructure
To demonstrate the viability of fine-tuning an open-weight decision model, engineers often turn to standardized benchmarks that reflect real-world linguistic diversity. The CLINC150 dataset serves as an ideal testbed, containing comprehensive intent categories spanning banking, travel, smart-home automation, and daily productivity assistant tasks. Originally designed to evaluate both in-scope intent classification and out-of-scope anomaly detection, the dataset comprises 15,000 training examples, 3,000 validation samples, and 4,500 test samples.
Executing the fine-tuning pipeline requires careful consideration of hardware constraints and software dependencies. While modern enterprise accelerators offer rapid training speeds, the experiment can be successfully executed within cloud-based development environments such as Google Colab utilizing standard consumer-grade hardware like an NVIDIA Tesla T4 GPU with approximately 14.6 GB of VRAM.
The software stack relies on optimized foundational components, specifically the Qwen3.5-4B model paired with the Unsloth optimization library. To mitigate memory overhead during the training phase, developers utilize 4-bit quantization alongside Low-Rank Adaptation (LoRA). This parameter-efficient fine-tuning methodology freezes the core weights of the foundational model while training a small percentage of additional parameters—specifically targeting the newly initialized decision head and designated LoRA adapters. Consequently, GPU memory consumption is drastically reduced while retaining the robust linguistic capabilities inherent in the base Qwen architecture.
Step-by-Step Implementation Chronology
The engineering workflow required to transform a foundational language model into a dedicated decision classifier follows a precise chronological sequence, moving from dependency configuration to evaluation and deployment.
-
Environment Initialization and Dependency Resolution: The initial phase involves configuring the execution environment by installing optimized versions of PyTorch, Transformers, and Unsloth via modern package managers like
uv. This ensures compatibility with custom GPU kernels and hardware acceleration primitives necessary for accelerated fine-tuning. -
Model Loading and Quantization: Rather than utilizing standard generative model loaders, the pipeline employs
FastDecisionModel.from_pretrainedto load the Qwen3.5-4B architecture under 4-bit quantization parameters. This step materializes the underlying language understanding capabilities while preparing the tensor spaces for the decision head. -
Parameter-Efficient Adaptation Configuration: LoRA parameters are subsequently applied to the model architecture. Setting the rank parameter to 16 with gradient checkpointing enabled allows the system to train approximately 2.10% of the total model parameters, effectively safeguarding against catastrophic forgetting while optimizing memory efficiency.
-
Dataset Ingestion and Preprocessing: The raw CLINC150 dataset is retrieved, and a subset of intents is isolated to maintain manageable sequence lengths and computational timelines for initial experimentation. These records are reformatted into the strict tripartite structure mandated by the decision-training protocol, which requires an input text state, a dictionary of structured questions and criteria, and a ground-truth label.
-
Baseline Evaluation: Prior to initiating gradient updates, the unoptimized decision model undergoes an initial evaluation phase against the validation dataset. Because the decision head is freshly initialized, its baseline accuracy typically mirrors random guessing—recording approximately 18.5% accuracy across a 10-intent classification subset, accompanied by higher expected calibration errors and loss values.
-
Supervised Fine-Tuning: Utilizing the specialized
DecisionTrainerclass, the model undergoes supervised fine-tuning across a defined schedule of training steps. Configured with optimized learning rate schedulers, cosine decay, and mixed-precision training (such as bfloat16 or float16 support), the system updates the trainable parameters over multiple epochs. During this phase, training and validation losses drop precipitously, signaling rapid convergence of the decision head. -
Post-Training Evaluation and Calibration: Upon completion of the training cycle, the model is re-evaluated against the validation and test splits. Following the optimization process, validation accuracy frequently reaches optimal levels, while expected calibration error metrics decline significantly, confirming that the model’s confidence scores accurately reflect its predictive certainty. Furthermore, built-in calibration methods can be invoked to further refine probability distributions.
Analysis of Empirical Results and Implications
Evaluating the fine-tuned Qwen3.5-4B decision model against held-out test data reveals profound implications for enterprise AI deployment. In controlled experimental runs utilizing a representative 10-intent subset of the CLINC150 benchmark, the model demonstrates a dramatic performance shift. Baseline accuracy figures of 18.5 percent escalate to optimal performance metrics following brief fine-tuning intervals lasting approximately 37 minutes on legacy hardware. More importantly, the evaluation confirms that the model successfully generalizes to unseen test items not encountered during the training or calibration phases.
However, industry analysts emphasize that while these empirical results validate the efficiency of the Unsloth decision-making framework, practical deployments require rigorous stress-testing against fully expanded intent spaces—such as the complete 150-category catalog—and ambiguous out-of-scope user queries. The ability of decision models to return granular probability distributions across all available options provides engineers with a transparent mechanism for establishing confidence thresholds. If a user query yields a top probability score below a predetermined operational threshold, the system can gracefully route the request to a human agent or trigger a fallback generative response, thereby mitigating the risks of automated misclassification.
Broader Industry Impact and Future Outlook
The maturation of decision-model training tools marks a pivotal shift in how organizations conceptualize large language models. Rather than treating LLMs exclusively as general-purpose text generators, enterprises are increasingly viewing them as versatile feature extractors that can be specialized for deterministic workflows. By decoupling the reasoning engine from the token generation loop, developers achieve unprecedented reductions in inference latency and computational overhead.
Frameworks like Unsloth democratize this capability, allowing development teams to fine-tune compact models on modest hardware infrastructures without sacrificing predictive accuracy. As businesses scale their reliance on autonomous agents, automated routing systems, and intelligent workflow orchestrators, the adoption of specialized decision models is poised to accelerate. This architectural paradigm ensures that artificial intelligence systems remain fast, transparent, and structurally aligned with the rigid data requirements of enterprise software engineering.