The rapid proliferation of Large Language Models (LLMs) across enterprise sectors has intensified discussions regarding cost-effective and computationally efficient adaptation strategies. When organizations seek to customize a pre-trained foundational model for a specific industry vertical or task—such as legal document classification, medical triage, or automated news categorization—machine learning engineers traditionally rely on exhaustive parameter updates. However, the economic and operational realities of cloud compute infrastructure, memory constraints, and latency requirements have forced a reevaluation of this paradigm.
Industry practitioners are increasingly weighing two distinct methodologies: parameter-efficient fine-tuning via Low-Rank Adaptation (LoRA) and the deployment of frozen embeddings coupled with lightweight downstream classifiers, such as those provided by the scikit-learn library. This comparative analysis examines the architectural mechanics, empirical performance, computational overhead, and strategic implications of both approaches, offering a comprehensive framework for machine learning architects tasked with balancing accuracy against operational expenditure.
Background and Context in Model Adaptation
Historically, adapting a foundational neural network to a downstream task required full-parameter fine-tuning. This process updates every weight matrix within the architecture, demanding massive VRAM allocations, robust hardware clusters, and substantial training durations. As model parameters scaled from millions to hundreds of billions, full fine-tuning became economically prohibitive for smaller organizations and resource-constrained engineering teams.
To democratize model customization, the research community introduced parameter-efficient fine-tuning (PEFT) techniques, most notably Low-Rank Adaptation (LoRA) and its quantized variant, QLoRA. These methods freeze the primary weights of the pre-trained model and inject trainable rank decomposition matrices into specific layers, significantly reducing the number of gradients that must be computed and stored.
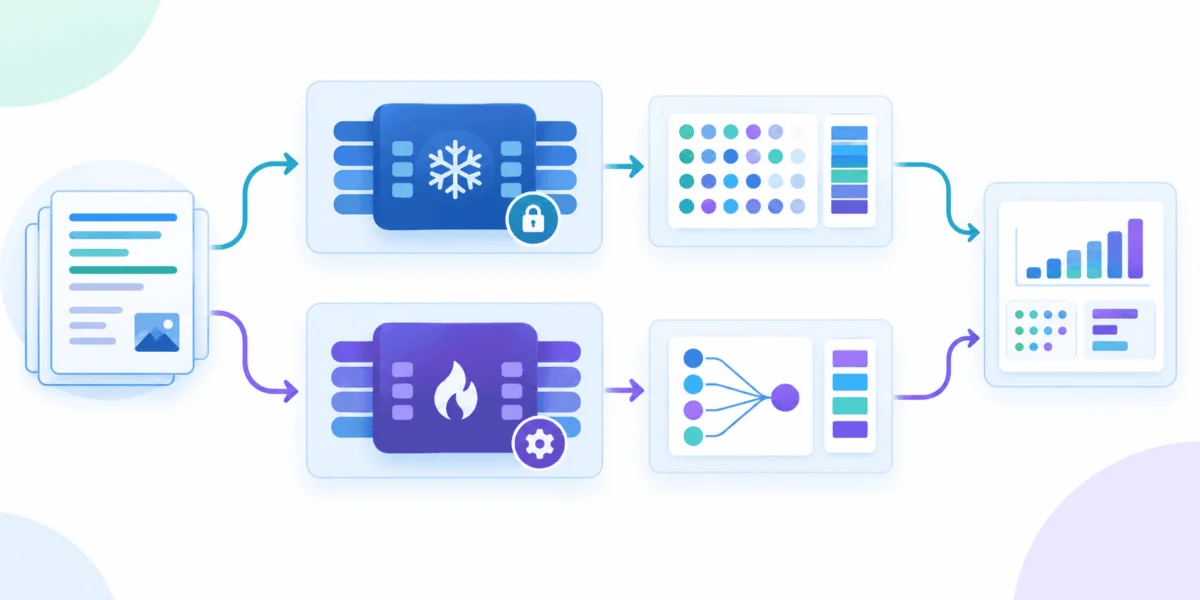
Concurrently, an alternative architectural pattern has gained traction: utilizing the pre-trained LLM strictly as a frozen feature extractor. Rather than modifying the network weights, input text is passed through the static model to extract high-dimensional hidden states—commonly referred to as embeddings. These representations are subsequently used to train a traditional, computationally inexpensive machine learning classifier, such as a Random Forest or Support Vector Machine (SVM). This approach eliminates the backpropagation phase entirely within the LLM backbone, shifting the training burden to lightweight statistical models.
Empirical Evaluation and Implementation Framework
To evaluate the operational trade-offs between these two strategies, engineers frequently utilize standardized classification benchmarks such as the AG News dataset, which categorizes news articles into four distinct classes: World, Sports, Business, and Sci/Tech.
Initial Environment Setup and Model Initialization
Executing a rigorous comparison requires a modern GPU environment (such as an NVIDIA T4 or higher) equipped with essential libraries including bitsandbytes, peft, accelerate, transformers, and scikit-learn. Modern decoder-only models, such as Qwen2.5-1.5B or Llama-3-8B, are typically loaded in a quantized 4-bit configuration utilizing NormalFloat4 (NF4) data types to minimize memory footprints while preserving numerical stability through bfloat16 compute types.
import torch
import numpy as np
import time
from datasets import load_dataset
from transformers import AutoTokenizer, AutoModelForSequenceClassification, BitsAndBytesConfig

MODEL_ID = "Qwen/Qwen2.5-1.5B"
dataset = load_dataset("fancyzhx/ag_news")
train_subset = dataset["train"].shuffle(seed=42).select(range(800))
test_subset = dataset["test"].shuffle(seed=42).select(range(200))

tokenizer = AutoTokenizer.from_pretrained(MODEL_ID)
tokenizer.pad_token = tokenizer.eos_token

bnb_config = BitsAndBytesConfig(
    load_in_4bit=True,
    bnb_4bit_compute_dtype=torch.bfloat16,
    bnb_4bit_quant_type="nf4"
)

model = AutoModelForSequenceClassification.from_pretrained(
    MODEL_ID,
    num_labels=4,
    quantization_config=bnb_config,
    device_map="auto"
)
model.config.pad_token_id = tokenizer.pad_token_id
Strategy A: Frozen Embeddings and Scikit-Learn Classifiers
The first methodology treats the large language model as an immutable feature generator. By disabling weight updates and passing input sequences through the model with the output_hidden_states=True parameter enabled, engineers can isolate the final hidden states. Applying mean pooling across the sequence length—while appropriately masking padding tokens—yields a dense embedding vector for each document.
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import accuracy_score

def extract_embeddings(texts, batch_size=8):
    model.eval()
    embeddings = []
    for i in range(0, len(texts), batch_size):
        batch = texts[i:i+batch_size]
        inputs = tokenizer(batch, return_tensors="pt", padding=True, truncation=True, max_length=128).to(model.device)
        with torch.no_grad():
            outputs = model(**inputs, output_hidden_states=True)
            last_hidden_state = outputs.hidden_states[-1]
            mask = inputs["attention_mask"].unsqueeze(-1).float()
            sum_embeds = torch.sum(last_hidden_state * mask, dim=1)
            mean_pooled = sum_embeds / torch.clamp(mask.sum(dim=1), min=1e-9)
            embeddings.append(mean_pooled.cpu().numpy().astype(np.float32))
    return np.concatenate(embeddings, axis=0)
Once the feature extraction phase concludes, these static vectors serve as the training matrix for a downstream classifier, such as a scikit-learn RandomForestClassifier.
In empirical testing on a subset of the AG News corpus, the feature extraction phase requires approximately 96.5 seconds, primarily driven by forward-pass inference overhead across the text batches. Conversely, training the Random Forest classifier on the extracted embeddings requires less than 3 seconds (specifically 2.866 seconds). This configuration yields a commendable test classification accuracy of 82.0%.
Strategy B: QLoRA Fine-Tuning
The second methodology abandons static feature extraction in favor of adapting the model architecture itself via Quantized Low-Rank Adaptation (QLoRA). By freezing the 4-bit base model and attaching trainable low-rank adapter matrices to targeted attention layers (such as q_proj and v_proj), engineers can restrict gradient updates to a negligible fraction—typically 1% to 2%—of the total parameter count.
from peft import LoraConfig, get_peft_model, prepare_model_for_kbit_training
from transformers import TrainingArguments, Trainer
import evaluate

model = prepare_model_for_kbit_training(model)
peft_config = LoraConfig(
    task_type="SEQ_CLS",
    r=16,
    lora_alpha=32,
    lora_dropout=0.05,
    target_modules=["q_proj", "v_proj"]
)
lora_model = get_peft_model(model, peft_config)

training_args = TrainingArguments(
    output_dir="./results",
    per_device_train_batch_size=8,
    per_device_eval_batch_size=8,
    learning_rate=2e-4,
    num_train_epochs=3,
    eval_strategy="epoch",
    logging_strategy="epoch",
    optim="paged_adamw_8bit",
    fp16=True,
    report_to="none"
)

trainer = Trainer(
    model=lora_model,
    args=training_args,
    train_dataset=tokenized_train,
    eval_dataset=tokenized_test,
    compute_metrics=compute_metrics,
)

start_time = time.time()
trainer.train()
lora_train_time = time.time() - start_time
Executing the QLoRA training loop across three epochs involves active backpropagation, optimizer state updates (optimized via paged AdamW in 8-bit), and gradient computations within the adapter weights. In comparative benchmarks, the training duration extends to approximately 300.3 seconds. However, this increased computational investment yields a performance dividend, raising test set accuracy to 87.0%.
Chronology and Operational Performance Summary
A structured review of the empirical metrics highlights the fundamental trade-off between computational expenditure and predictive performance:
| Performance Metric | Strategy A: Frozen Embeddings + Random Forest | Strategy B: QLoRA Fine-Tuning |
|---|---|---|
| Primary Process Time | ~96.5 seconds (Feature Extraction) | ~300.3 seconds (Model Training) |
| Downstream Train Time | 2.866 seconds | N/A (Integrated Training) |
| Test Accuracy | 82.0% | 87.0% |
| Memory Overhead | Low (Inference-only VRAM footprint) | Moderate (Requires gradient storage for adapters) |
| Architectural Flexibility | High (Easily swap classifiers) | Low (Model weights are structurally altered) |
Industry Implications and Strategic Recommendations
The selection between frozen embeddings and LoRA fine-tuning cannot be reduced to a binary preference for maximum accuracy; rather, it requires a nuanced assessment of engineering constraints, deployment environments, and business objectives.
When building rapid prototypes, cost-sensitive microservices, or applications operating under strict latency and compute budgets, the frozen embedding strategy offers distinct advantages. By decoupling the feature extraction phase from the classification model, developers can cache vector representations, experiment with diverse scikit-learn algorithms (such as gradient boosting, support vector machines, or logistic regression) instantaneously, and eliminate the complexities associated with managing gradient computations during deployment. Furthermore, this approach completely avoids backbone overfitting, making it robust when training data is severely limited.
Conversely, QLoRA fine-tuning remains indispensable when absolute predictive accuracy is paramount. In highly specialized vertical domains—such as legal contract analysis, proprietary financial auditing, or complex biomedical classification—the subtle semantic nuances required to push accuracy from 82% to 87% (or higher) necessitate direct adaptation of the model’s internal representations. Although training times triple and infrastructure requirements increase, the resulting model captures domain-specific syntax and terminology in a manner that external classifiers operating on static embeddings cannot fully replicate.
For purely generative tasks, such as open-ended text generation, conversational agents, or automated code synthesis, frozen embeddings are generally insufficient, as the model must actively generate novel token sequences aligned with domain-specific formatting and logic. In those contexts, parameter-efficient fine-tuning is mandatory. Ultimately, machine learning engineers must weigh the marginal gains in model accuracy against the cumulative costs of cloud compute time, maintenance complexity, and deployment scalability.