
The rapid advancement of artificial intelligence has largely been defined by how systems process information, shifting from unimodal text comprehension to complex, multi-modal synthesis. While standard Retrieval-Augmented Generation (RAG) frameworks have proven remarkably effective for plain-text databases, they routinely falter when confronted with enterprise documents that synthesize prose, complex data tables, scanned diagrams, and embedded charts. Traditional text-based chunking protocols inherently destroy table formatting, skip embedded graphics, and ignore visual context, leaving enterprise AI applications with a severely fragmented understanding of core reference materials.
To bridge this operational gap, developers and enterprise architects are increasingly turning to multi-modal RAG pipelines. By treating images, tables, and visual artifacts as first-class retrievable objects alongside traditional text elements, modern frameworks can parse, index, and reason across heterogeneous data sources. This technical blueprint explores how to construct a robust, API-driven multi-modal RAG system using Python, LangChain, the Unstructured library, and OpenAI’s GPT-4o, providing a scalable architecture tailored for business intelligence, financial auditing, and academic research.
The Evolution of Document Retrieval: Moving Beyond Plain Text
The limitations of text-only RAG frameworks are well-documented within the machine learning community. When a Large Language Model (LLM) is asked to evaluate a comprehensive corporate financial report, a dense technical whitepaper, or an engineering schematic, the underlying data is rarely limited to sequential strings of text. Vital operational metrics are frequently housed in graphical charts, architectural diagrams, or multi-column data tables.
In a conventional RAG pipeline, a PDF parser extracts raw character streams, stripping away spatial layouts and ignoring images entirely. Consequently, when a user queries the system, the vector database retrieves incomplete context, forcing the LLM to hallucinate or state that the information is unavailable.
Multi-modal AI architectures resolve this deficiency by unifying text and vision processing. Rather than forcing visual assets into a textual paradigm, modern architectures ingest diverse modalities, generate semantic text summaries for non-textual assets, and store them within an interconnected multi-vector retrieval structure. While local approaches—such as PyTorch-based implementations utilizing specialized vision encoders—are ideal for edge computing or heavy multimedia workloads, API-driven architectures provide a scalable, hardware-efficient alternative suitable for standard enterprise infrastructure.
Prerequisites and System Configuration
Deploying a production-grade multi-modal RAG pipeline requires specific software libraries capable of handling multi-format document parsing and vector embedding operations. Developers must configure an environment equipped with Python, LangChain, ChromaDB, and the Unstructured ecosystem.
pip install langchain langchain-openai unstructured[pdf] chromadb pillow
apt-get install -y poppler-utils
The inclusion of poppler-utils is a critical system-level dependency required by the Unstructured library to accurately render and extract embedded image blocks from PDF files. Once the packages are installed, developers must provision an active OpenAI API key within their runtime environment to authorize calls to the embedding endpoints and the GPT-4o vision model.
import os

os.environ["OPENAI_API_KEY"] = "your-api-key-here"
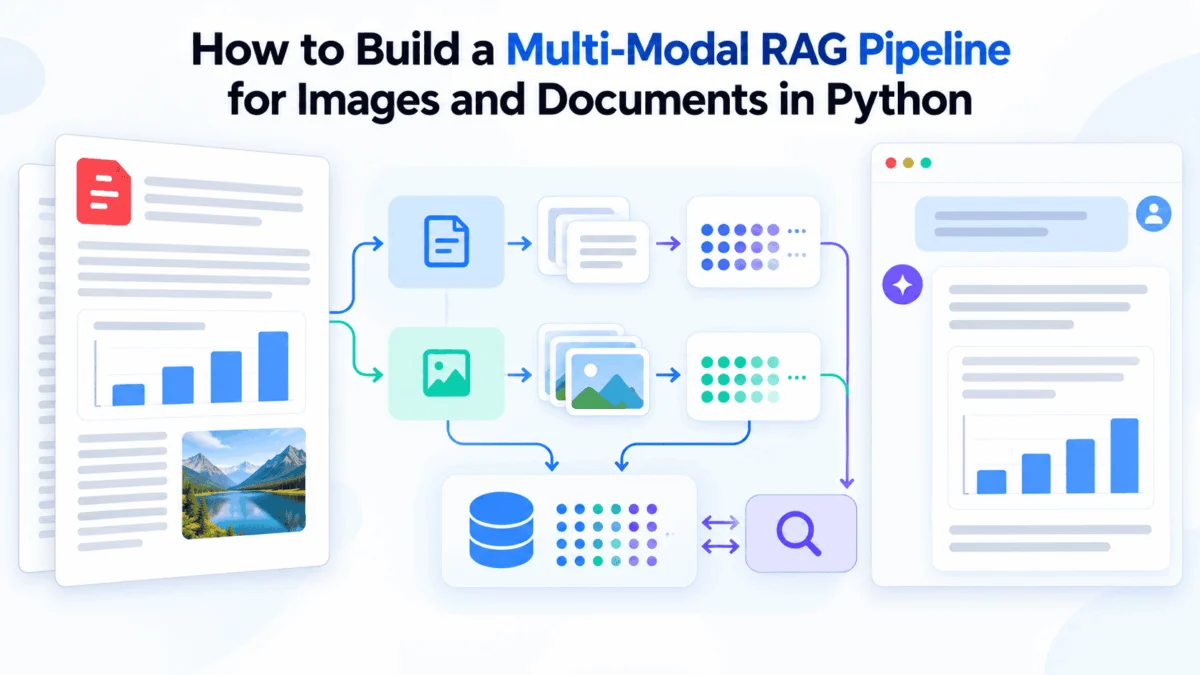
The operational workflow of the pipeline follows a sequential, four-stage lifecycle: parsing raw documents, generating searchable image summaries, populating a multi-vector store, and executing context-aware multi-modal queries.
Stage 1: Document Parsing and Modality Separation
The initial phase of the pipeline involves ingesting a complex document and separating its constituent parts. The unstructured library executes this function via its partition_pdf() method, which classifies document elements by structural type—distinguishing between narrative paragraphs, section headers, tabular data, and embedded images.
from unstructured.partition.pdf import partition_pdf

raw_elements = partition_pdf(
    filename="report.pdf",
    extract_image_block_types=["Image"],
    extract_image_block_output_dir="./extracted_images",
    infer_table_structure=True,
    chunking_strategy="by_title",
    max_characters=4000,
)
By configuring parameters such as extract_image_block_output_dir and infer_table_structure, the parsing engine preserves the spatial integrity of tables while isolating visual elements into designated file directories. Following ingestion, the raw elements are filtered into distinct text and image collections for downstream indexing.
text_elements = []
image_paths = []

for el in raw_elements:
    if "CompositeElement" in str(type(el)):
        text_elements.append(str(el))
    elif "Image" in str(type(el)):
        image_paths.append(el.metadata.image_path)

print(f"Extracted len(text_elements) text chunks, len(image_paths) images")
Stage 2: Semantic Image Summarization
Standard text-based vector databases cannot natively index raw image files, as vector embeddings rely on textual or numerical tensor spaces. To overcome this limitation, every extracted image must undergo a summarization process that translates visual data into rich, natural language descriptions optimized for semantic search.
This phase leverages OpenAI’s GPT-4o model. Each extracted image is opened, encoded into a Base64 string, and transmitted to the model alongside a retrieval-focused prompt.
import base64
from openai import OpenAI

client = OpenAI()

def summarize_image(image_path):
  with open(image_path, "rb") as f:
    image_data = base64.b64encode(f.read()).decode("utf-8")

  response = client.chat.completions.create(
      model="gpt-4o",
      messages=[
          "role": "user",
          "content": [

                  "type": "image_url",
                  "image_url":
                      "url": f"data:image/png;base64,image_data"
                  ,
              ,

                  "type": "text",
                  "text": "Describe this image in detail for use in a search system.",
              ,
          ],
      ],
  )
  return response.choices[0].message.content

image_summaries = [summarize_image(p) for p in image_paths]
The resulting text summaries act as searchable proxies for the underlying visual assets. While the raw image files are preserved separately in local storage, their generated summaries are embedded within the vector space, allowing natural language queries to successfully locate charts, graphs, and diagrams.
Architectural analysts note that while this approach maximizes retrieval accuracy, developers must monitor API usage costs. Large documents containing numerous decorative logos or low-value icons should incorporate file-size filtering mechanisms prior to summarization to prevent unnecessary API overhead.
Stage 3: Establishing the Multi-Vector Store Architecture
Unlike conventional RAG setups that maintain a singular vector store index, multi-vector retrieval frameworks utilize a dual-storage paradigm. A vector store (such as ChromaDB) indexes embedded text chunks and image summaries for high-speed similarity search, while an independent document store (InMemoryStore) preserves the original, uncompressed source content linked via unique universally unique identifiers (UUIDs).
import uuid
from langchain_chroma import Chroma
from langchain_core.documents import Document
from langchain_openai import OpenAIEmbeddings
from langchain.retrievers.multi_vector import MultiVectorRetriever
from langchain.storage import InMemoryStore

embeddings = OpenAIEmbeddings(model="text-embedding-3-small")
vectorstore = Chroma(embedding_function=embeddings)
docstore = InMemoryStore()

retriever = MultiVectorRetriever(
    vectorstore=vectorstore, docstore=docstore, id_key="doc_id"
)

text_ids = [str(uuid.uuid4()) for _ in text_elements]
image_ids = [str(uuid.uuid4()) for _ in image_summaries]
Once the stores are initialized and unique identifiers are assigned, both text elements and image summaries are injected into the vector database. Simultaneously, the raw documents and image paths are mapped to their corresponding identifiers within the document store.
retriever.vectorstore.add_documents([
    Document(page_content=t, metadata="doc_id": i)
    for t, i in zip(text_elements + image_summaries, text_ids + image_ids)
])

raw_docs = [Document(page_content=t, metadata="type": "text") for t in text_elements] + [
    Document(page_content=p, metadata="type": "image") for p in image_paths
]

retriever.docstore.mset(list(zip(text_ids + image_ids, raw_docs)))
This structural separation ensures that embedding models perform similarity matching against clean, descriptive prose, while the generation phase receives the exact source artifact—whether text block or high-resolution image file.
Stage 4: Query Execution and Multimodal Synthesis
When an end user submits a query to the pipeline, the retriever embeds the incoming question and executes a similarity search across the vector store. Matches can point to either standard text chunks or image summaries.
If a retrieved document carries an image metadata classification, the system dynamically loads the local image file, encodes it into Base64 format, and formats it for multimodal LLM consumption alongside any retrieved text passages.
def query_pipeline(question):
  docs = retriever.invoke(question)
  text_content, image_content = [], []

  for doc in docs:
    if doc.metadata.get("type") == "image":
      with open(doc.page_content, "rb") as f:
        img_b64 = base64.b64encode(f.read()).decode("utf-8")
      image_content.append(
          "type": "image_url",
          "image_url": "url": f"data:image/png;base64,img_b64",
      )
    else:
      text_content.append("type": "text", "text": doc.page_content)

  response = client.chat.completions.create(
      model="gpt-4o",
      messages=[
          "role": "user",
          "content": (
              text_content
              + image_content
              + ["type": "text", "text": question]
          ),
      ],
  )
  return response.choices[0].message.content

answer = query_pipeline("What does the revenue chart show for Q3?")
print(answer)
Through this architecture, GPT-4o synthesizes cross-modal evidence, evaluating qualitative textual disclosures alongside quantitative visual data before formulating a comprehensive, grounded response.
Implications, Scalability, and Future Outlook
The deployment of multi-vector, multimodal RAG pipelines represents a significant maturation point for enterprise artificial intelligence applications. By resolving the longstanding blind spot regarding non-textual document components, organizations can reliably automate document analysis across complex domains such as medical research, patent law, financial auditing, and technical manufacturing.
Industry analysts observe that while API-driven frameworks offer rapid deployment cycles and manageable hardware requirements, production scaling requires careful attention to persistence layers and retrieval precision. Enterprises moving beyond local in-memory stores typically transition to persistent vector storage engines like Chroma or Pinecone, paired with advanced re-ranking algorithms to optimize retrieval accuracy. Furthermore, emerging paradigms—such as native vision-language embedding models (e.g., ColPali)—signal a future where intermediate parsing steps may be bypassed entirely, allowing vision encoders to index document pages directly as visual tokens.
Ultimately, transitioning from text-bound systems to multi-modal RAG infrastructures ensures that enterprise AI applications can comprehend documentation with the same contextual depth and visual awareness as human analysts.