

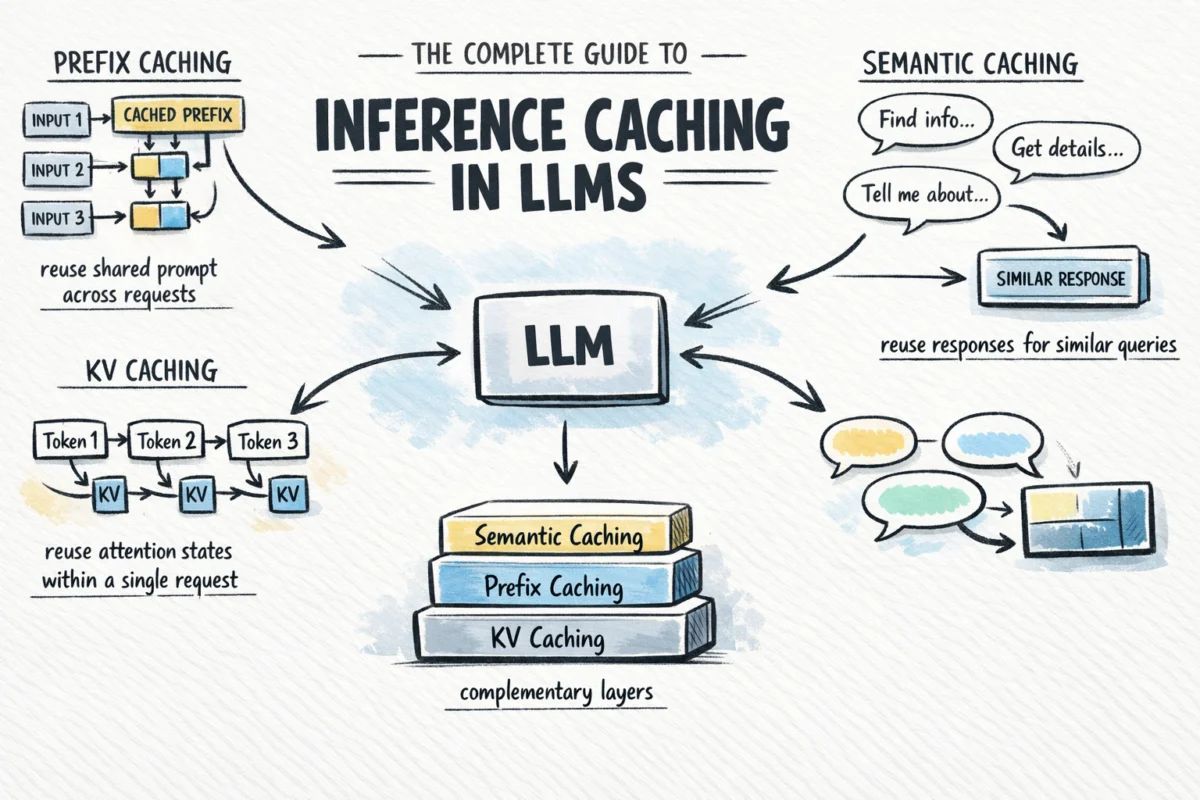
The Complete Guide to Inference Caching in LLMs: Strategies for Reducing Cost and Latency in Production AI Systems
The rapid proliferation of large language models (LLMs) in enterprise environments has brought a critical challenge to the forefront of...