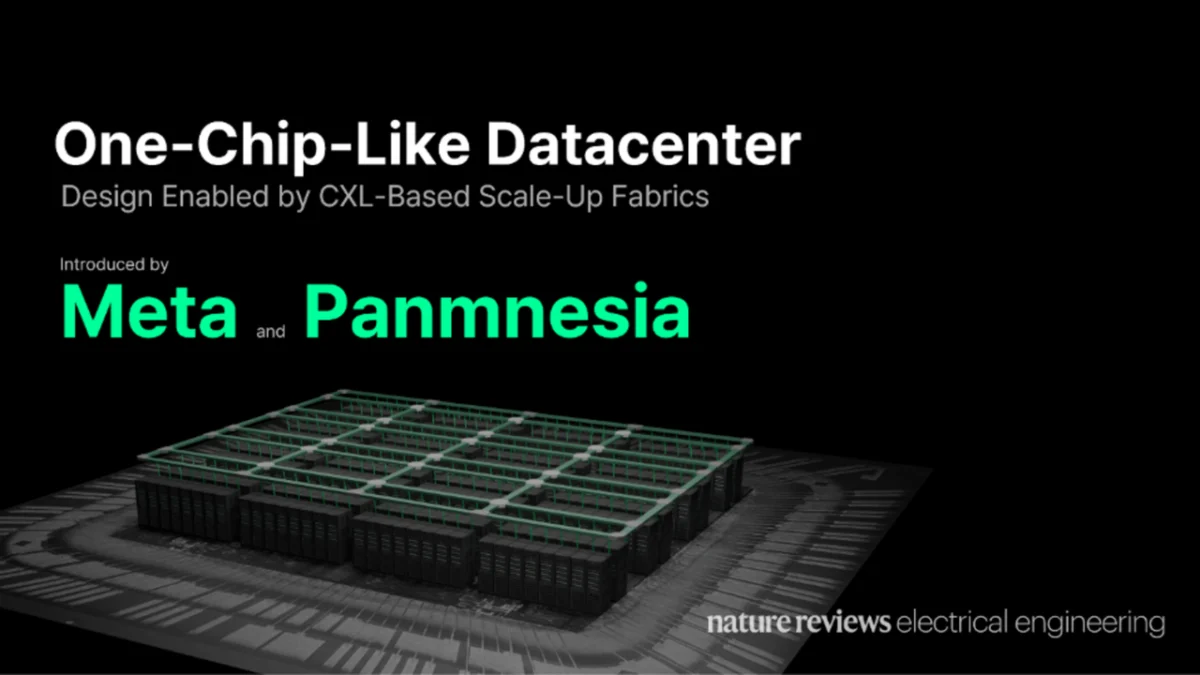
Meta is collaborating with semiconductor startup Panmnesia to develop a groundbreaking artificial intelligence data center architecture designed to unify thousands of processors into a single, highly coherent computing environment. By leveraging Compute Express Link (CXL) technology, the ambitious proposal seeks to connect central processing units (CPUs), specialized AI accelerators, and memory pools across multiple server racks, bypassing the latency bottlenecks traditionally associated with conventional networking links like Ethernet and InfiniBand.
The innovative blueprint aims to integrate up to 960 AI accelerators into a singular coherence domain. This unprecedented scale would allow nearly 1,000 graphics processing units (GPUs) and specialized accelerators to operate in unison as one massive, monolithic system. As generative AI models grow exponentially in parameter size and computational demand, the infrastructure required to train them efficiently has become one of the most critical engineering challenges in the technology sector.
The Bottleneck of Modern AI Training Infrastructures
Modern artificial intelligence training is an intensely collaborative and synchronized process. Large-scale models, such as advanced foundational large language models (LLMs), distribute their workloads across hundreds or thousands of accelerators simultaneously. These devices must constantly communicate, exchanging intermediate computational outputs at every single training stage.
In this environment, the system is only as fast as its slowest component. If a single accelerator experiences a communication delay or a network stall, all other interconnected devices must pause their computations and wait for the delayed data to arrive. Consequently, minimizing unpredictable communication latency—known as jitter—is paramount for maximizing hardware utilization and reducing training times, which can otherwise stretch across weeks or months.
Traditionally, hyperscale data centers rely on high-speed networking solutions such as Ethernet or InfiniBand to link servers across different racks. While these networking protocols are robust, they introduce significant overhead. They require complex packet processing, buffer management, and extensive software stack coordination. As workloads scale across an increasing number of servers, this overhead compounds, leading to unpredictable latency spikes and degraded overall system performance.
CXL as the Ultimate Unified Fabric Solution
To eliminate these networking overheads, Meta and Panmnesia’s proposed architecture turns to Compute Express Link (CXL). CXL is an industry-standard cache-coherent interconnect built on top of the physical PCI Express (PCIe) infrastructure. It provides a shared memory and coherence mechanism, allowing CPUs, memory expanders, and hardware accelerators to interact within a unified, natively addressed resource pool.
Under this paradigm, accelerators do not need to package data into network packets and decode them upon arrival. Instead, they can read and write directly to shared memory spaces as if all components were housed on the same motherboard.
To make this feasible across an entire data center scale, Panmnesia has engineered a specialized hardware suite. The proprietary design incorporates a high-fan-out CXL switch, a dedicated link acceleration unit, and a sophisticated fabric controller. These components are meticulously organized into structural trays and pods, borrowing organizational principles typically reserved for designing the internal functional blocks of microprocessors, effectively treating the entire data center like a single super-chip.
Significant Milestones in Silicon Validation
The development of this infrastructure has moved rapidly through initial engineering phases. Panmnesia has confirmed that major building blocks of its architecture have already reached critical manufacturing and testing milestones.
The company’s advanced fabric controller and link acceleration units have successfully completed silicon validation, proving their reliability and functional readiness in physical hardware. Meanwhile, the high-fan-out CXL switch has already been fully fabricated, with pre-release silicon samples currently being distributed to key partners and developers for integration testing and evaluation.
These milestones indicate that the technology is transitioning smoothly from theoretical systems architecture into viable commercial products. While enterprise-wide deployment will require rigorous testing in live hyperscale environments, the successful fabrication of foundational silicon proves that hardware manufacturers are overcoming the physical and electrical barriers of CXL scaling.
Scaling Up: 960 Accelerators in a Single Domain
To understand the magnitude of Panmnesia’s proposal, industry analysts often compare it to existing market benchmarks, such as NVIDIA’s state-of-the-art GB200 NVL72 architecture. In NVIDIA’s reference configuration, a single CPU directly coordinates two accelerators via proprietary NVLink-C2C (Chip-to-Chip) connections.
Panmnesia’s architecture drastically expands this ratio. Under their proposed framework, a single CPU can coordinate up to 16 accelerators—representing an eightfold increase in coordination efficiency compared to current industry standards. By grouping roughly 60 of these configurations together, the system successfully forms a massive coherence domain containing approximately 960 accelerators.
Furthermore, the physical benefits of this layout are profound. Cross-rack access latency, which typically lingers in the microsecond range over traditional network cables, is projected to drop to several hundred nanoseconds. This represents roughly an order-of-magnitude reduction in communication latency, vastly accelerating the synchronization phase of large-scale AI training pipelines.
Resilience and Maintenance Advantages
Beyond raw speed and computational scaling, the Meta-Panmnesia architecture introduces structural advantages in hardware maintenance and system reliability. In standard rack designs, if a critical component or accelerator fails within a server blade, the entire server often has to be taken offline, interrupting workloads and complicating maintenance routines.
The CXL-based fabric architecture allows for granular device isolation. Individual failed hardware units can be hot-swapped or replaced independently without taking an entire server out of service. This modularity reduces the amount of functioning hardware unnecessarily removed during routine maintenance or component failures, translating to higher uptime and reduced operational expenditure for hyperscale operators.
Myoungsoo Jung, CEO of Panmnesia, underscored the transformative potential of this technology during the architectural unveiling, stating, “CXL enables the entire datacenter to operate as a single computing system.”
Overcoming Physical Limitations with Optical Interconnects
Despite its immense promise, electrical CXL signaling faces strict physical boundaries. Standard copper-based electrical CXL signals degrade over distance, typically reaching a maximum span of about seven meters even when utilizing two retimers to boost the signal integrity at 128 GT/s (Gigatransfers per second). This physical limitation restricts how far apart server racks can be placed while maintaining low-latency coherence.
To solve this challenge, Panmnesia has integrated optical CXL links into its long-term roadmap. By transitioning from copper wiring to optical fiber transceivers, the architecture can span across massive data center floors without suffering from signal degradation or latency penalties. Panmnesia reports that it has already completed hardware proof-of-concept validation for its optical CXL approach, ensuring the design can scale beyond the physical confines of a single server row.
Broader Industry Implications and Future Outlook
The collaboration between Meta and Panmnesia marks a pivotal shift in how hyperscale data centers are conceptualized. As artificial intelligence models demand increasingly vast computational pools, relying solely on traditional networking topologies is no longer sustainable.
By pushing CXL technology to its absolute limits—and expanding coherence domains to nearly 1,000 accelerators—this partnership points toward a future where hardware silos are entirely dismantled. If commercialized successfully, this architecture could drastically reduce the energy consumption, time, and financial capital required to train the next generation of artificial intelligence systems, cementing a new standard for high-performance computing infrastructure worldwide.