

The rapid expansion of enterprise artificial intelligence has forced engineering teams to confront a persistent architectural dilemma: when tailoring a large language model (LLM) to a specialized vertical, should developers invest compute resources into parameter-efficient fine-tuning, or is it more efficient to treat the model as a static feature extractor paired with a classical machine learning classifier? This question strikes at the heart of cost-optimization strategies for production-grade natural language processing systems, balancing the trade-offs between computational overhead, inference latency, and predictive accuracy.
Historically, the machine learning community has leaned heavily toward full or parameter-efficient fine-tuning as the default standard for domain adaptation. However, as organizations increasingly deploy models under strict budgetary and infrastructure constraints, alternative paradigms—such as utilizing frozen embeddings paired with lightweight scikit-learn classification heads—have gained traction. To evaluate these competing approaches objectively, recent technical benchmarks provide a clear performance and cost analysis comparing Low-Rank Adaptation (LoRA) against downstream classical classifiers.
Background and Context of LLM Domain Adaptation
Large language models trained on massive, generalized corpora possess broad linguistic competence, yet they frequently underperform when applied to narrow, domain-specific tasks such as legal document categorization, medical diagnostics routing, or financial sentiment analysis. Bridging this performance gap requires steering the model toward the target domain’s semantic distribution.
Traditionally, adaptation involved adjusting all parameters within the neural network, a process computationally prohibitive for modern multi-billion parameter architectures. This led to the widespread adoption of parameter-efficient fine-tuning (PEFT) methodologies, most notably Low-Rank Adaptation (LoRA) and its quantized variant, QLoRA. By freezing the original pre-trained weights and injecting small, trainable rank decomposition matrices into the attention layers, QLoRA drastically reduces memory consumption while preserving model plasticity.
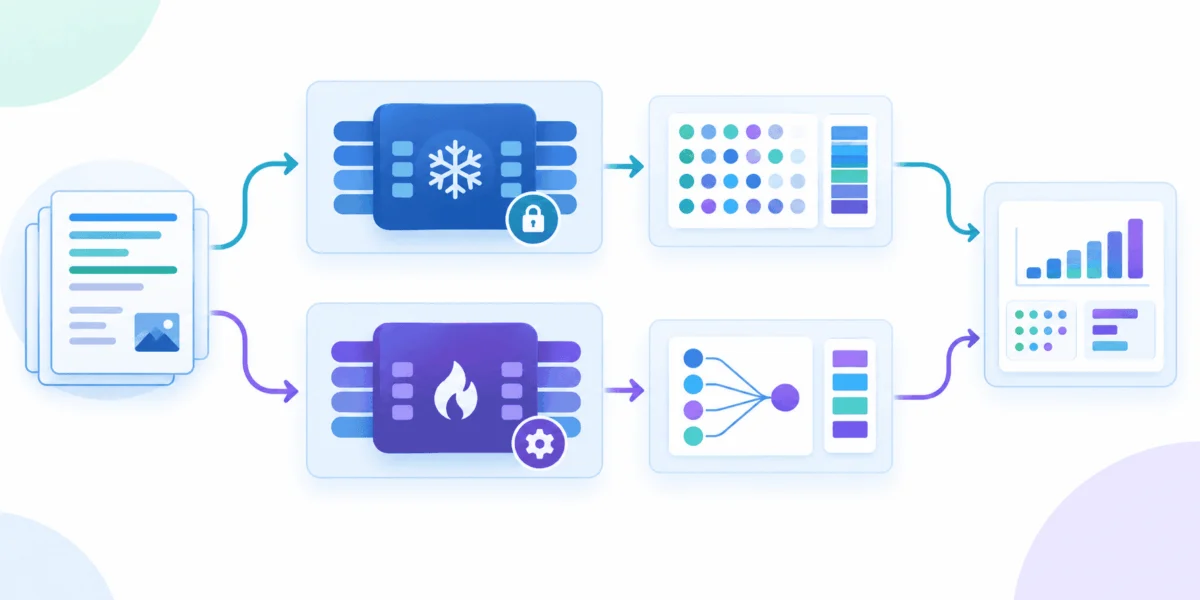
Simultaneously, an alternative architecture has emerged for classification tasks: the frozen embedding strategy. In this pipeline, the base LLM’s weights are entirely locked. Input texts are passed through the frozen network to extract high-dimensional hidden states—typically derived from the final token or pooled across sequence outputs—which are subsequently fed into traditional machine learning algorithms like random forests or support vector machines. Proponents of this approach highlight its near-instantaneous training cycles for the downstream classifier and the elimination of catastrophic forgetting within the foundational LLM backbone.
Comparative Benchmarking Methodology
To quantify the differences between these two methodologies, engineers implemented a controlled comparative benchmark utilizing a consumer-grade GPU environment (specifically, an NVIDIA T4 via Google Colab). The evaluation framework utilized a subset of the canonical ag_news classification dataset, comprising 800 training samples and 200 test samples categorized into four distinct news topics.
The baseline model selected for the experiment was Qwen/Qwen2.5-1.5B, loaded in a 4-bit quantized format using the bitsandbytes library to optimize memory efficiency. The experiment evaluated two distinct implementation pathways:
- Strategy A (Frozen Embeddings & Scikit-Learn): The base model acted strictly as a feature extractor. Input sequences were processed through the 4-bit model without weight updates. Mean-pooled hidden state vectors were extracted from the final hidden layers and used to train a standard scikit-learn
RandomForestClassifierconsisting of 100 estimators. - Strategy B (QLoRA Fine-Tuning): Low-Rank Adaptation adapters were attached to the attention projection layers (
q_projandv_proj) with a rank ($r$) of 16 and an alpha scaling parameter of 32. The model was trained using Hugging Face’sTrainerAPI over three epochs with a learning rate of $2e-4$, utilizing paged 8-bit AdamW optimization.
Chronology and Execution Metrics
The execution timeline highlights stark differences in computational resource utilization and time-to-deployment between the two approaches.
For Strategy A, the feature extraction phase—requiring sequential batch processing of the text corpus through the frozen 4-bit LLM—consumed approximately 96.5 seconds. Once the high-dimensional vector representations were generated, the training of the downstream scikit-learn Random Forest classifier was executed in just 2.866 seconds. Evaluation on the 200-sample test set yielded an overall classification accuracy of 82.0%. The entire pipeline demonstrated rapid iteration capability, albeit with the heavy initial bottleneck of embedding generation.
Conversely, Strategy B required a substantially more intensive training cycle. The QLoRA fine-tuning process, operating across three full epochs over the training subset, required 300.3 seconds—roughly triple the duration of Strategy A’s total pipeline time. However, this increased computational investment translated into measurable performance gains, yielding a final test classification accuracy of 87.0%.
| Strategy | Primary Mechanism | Training / Processing Time | Test Accuracy | Computational Overhead |
|---|---|---|---|---|
| Strategy A | Frozen LLM + Random Forest | 99.4s total (96.5s extraction) | 82.0% | Low (Instant classifier fit) |
| Strategy B | QLoRA Fine-Tuning (3 Epochs) | 300.3s total | 87.0% | Moderate-High (Full gradient updates via adapters) |
Technical Implications and Industry Analysis
The empirical findings underscore a fundamental trade-off between engineering velocity and predictive ceiling.
Feeding frozen embeddings into classical auxiliary models offers distinct operational advantages. Because the underlying LLM backbone remains untouched, the risk of catastrophic forgetting—where a model loses its generalized linguistic capabilities during domain adaptation—is entirely neutralized. Furthermore, the downstream classifier can be swapped, tuned, or retrained in seconds without re-running expensive gradient-based optimization on transformer weights. This architecture is exceptionally well-suited for resource-constrained environments, rapid prototyping, and scenarios where infrastructure budgets preclude multi-epoch GPU training jobs.
On the other hand, QLoRA fine-tuning remains the superior choice when absolute predictive accuracy is paramount. By actively modifying the network’s internal representations via low-rank adapters, the model develops a nuanced, deeply integrated understanding of domain-specific vocabulary and syntactic structures that static embeddings often fail to capture. While the training duration scales up significantly—a factor that becomes acutely pronounced when moving from hundreds of samples to hundreds of thousands—the 5% accuracy improvement observed in the benchmark demonstrates the tangible value of adapter-based adaptation.
Industry analysts note that this calculus shifts entirely depending on the operational objective. For generative tasks—such as automated summarization, conversational agents, or source code synthesis—frozen embedding strategies are fundamentally inadequate, as text generation requires active weight adaptation to shape output formatting and stylistic adherence. For classification and retrieval-augmented generation (RAG) routing systems, however, the choice between a frozen embedding head and a fine-tuned adapter remains an organization-specific decision balancing infrastructure costs against performance margins.
Broader Impact on Enterprise AI Deployment
As enterprises transition from experimental artificial intelligence deployments to hardened, production-level architectures, cost-awareness has taken center stage. Engineering leadership teams are increasingly auditing their pipelines to eliminate unnecessary compute expenditures.
The viability of frozen embedding classifiers suggests that organizations do not always need to deploy heavy fine-tuning pipelines for standard text categorization tasks. By leveraging smaller, highly efficient open-weights models as feature extractors paired with traditional machine learning models, companies can achieve robust baseline performance at a fraction of the operational cost. Conversely, mission-critical applications where marginal accuracy gains translate directly into financial or operational value will continue to justify the computational investment of parameter-efficient fine-tuning frameworks like QLoRA. Ultimately, architectural selection must be dictated by a rigorous evaluation of dataset scale, latency requirements, and the cost-per-accuracy threshold of the specific business vertical.