The artificial intelligence landscape is undergoing a profound structural shift as model distillation—once viewed as a routine optimization technique—becomes the center of fierce intellectual property battles. As foundation models scale to hundreds of billions of parameters, consuming vast computational resources and hundreds of millions of dollars to train, the methods used to compress these systems into nimble, deployable assets are drawing intense legal, political, and commercial scrutiny.
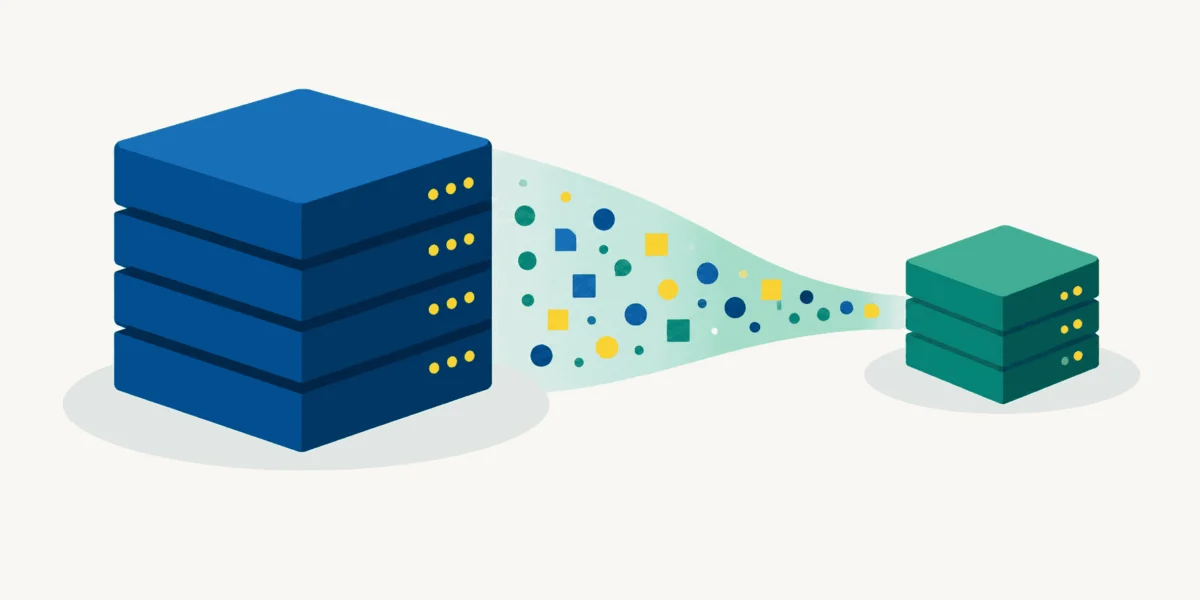
At its core, model distillation involves transferring the capabilities of a massive "teacher" model to a significantly smaller "student" model. While major artificial intelligence laboratories routinely employ this technique internally to build efficient commercial tiers, the industry is now grappling with a wave of allegations concerning systematic, unauthorized distillation at a global scale. This tension highlights an unresolved vulnerability in the economics of generative AI: how to make advanced intelligence commercially accessible through application programming interfaces (APIs) without enabling competitors to cheaply replicate foundational research.
The Evolution of Distillation: From Dark Knowledge to Synthetic Scale
To understand the current controversies, one must examine how knowledge transfer has evolved since Geoffrey Hinton, Oriol Vinyals, and Jeff Dean published their foundational framework in 2015. Classical distillation was designed for tasks with fixed output classes, such as image classification or speech recognition. In standard training, models learn from hard binary labels—identifying an image definitively as a dog or a cat. However, hard labels discard rich relational context. A trained teacher model outputs a probability distribution—for example, assessing an image as 85 percent dog, 13 percent cat, and 2 percent wolf. Hinton famously described the information embedded in these distributions as "dark knowledge," capturing the model’s learned sense of similarity between concepts.
By training a smaller student model on these softened probability distributions using a technique called temperature scaling, engineers could transfer the generalization capabilities of an ensemble model into a compact footprint.
Large language models (LLMs), however, shattered the applicability of classical logit-based distillation. Generating text token by token across vocabularies exceeding 100,000 words requires a sequential, probabilistic structure that simple categorical matching cannot capture. Consequently, modern distillation has branched into three distinct methodologies:
- Synthetic Data Generation: The current dominant paradigm, wherein a teacher model generates massive volumes of high-quality reasoning chains, code solutions, and structured text. A student model is then fine-tuned directly on this synthetic dataset. Crucially, this approach requires only black-box API access to the teacher’s text outputs rather than internal architectural visibility.
- Feature Distillation: A white-box method where the student learns to replicate the teacher’s internal representations and intermediate layer activations, transferring a deeper structural understanding of information processing.
- Logit-Based Token Distillation: An adaptation of classical techniques matching full token probability distributions, restricted to organizations with internal access to model weights.
This methodological split carries immense commercial weight. Because synthetic data distillation requires only an internet connection and an active API subscription, it opened the floodgates for external entities to extract advanced reasoning capabilities from proprietary systems.
Chronology of Escalation: Allegations and Disclosures
The debate shifted from theoretical optimization to high-stakes geopolitics and corporate warfare in early 2026. Major artificial intelligence laboratories stepped forward with public disclosures detailing coordinated, large-scale campaigns aimed at harvesting their proprietary models.
- Early 2026: OpenAI submitted a formal memorandum to the United States House Select Committee on China. The document alleged that Chinese lab DeepSeek had utilized obfuscated extraction methods, including third-party routing, to systematically siphon capabilities from OpenAI models during its development cycles.
- Spring 2026: Anthropic published forensic accounts detailing approximately 24,000 fraudulent accounts generating over 16 million interactions with its Claude model. The activity specifically targeted high-value, highly differentiated capabilities, including agentic reasoning, complex tool use, and advanced software engineering. Concurrently, Google disclosed that its Threat Intelligence Group had identified and disrupted parallel distillation attacks involving more than 100,000 adversarial prompts directed at Gemini.
- April 2026: During legal depositions in his ongoing lawsuit against OpenAI, xAI founder Elon Musk acknowledged under oath that his company had "partly" utilized OpenAI models in training the Grok architecture, defending the practice as an open industry norm.
- June 2026: Anthropic publicly accused Alibaba’s Qwen research lab of orchestrating the largest known extraction campaign to date. According to Anthropic’s telemetry, approximately 25,000 fake user accounts executed 28.8 million targeted exchanges with Claude over a compressed 44-day window. Representatives for Alibaba formally denied the allegations.
Economic Discrepancies and the Cost of R&D
The controversy is heavily underscored by intense debates over the true cost of frontier AI development. When DeepSeek released its technical reports indicating that training its V3 model required a modest compute expenditure of roughly $5.6 million, it sent shockwaves through global financial markets and depressed valuations for Western semiconductor and infrastructure firms.
However, independent industry analyses—such as those published by SemiAnalysis—estimated the true economic investment closer to $1.3 billion when accounting for cumulative foundational research, algorithmic iteration, and supporting infrastructure. Critics and rival labs argue that if unauthorized synthetic distillation is occurring at scale, externalized R&D costs allow efficient followers to bypass the multi-billion-dollar exploratory phase of model training. By harvesting the reasoning traces of models that cost hundreds of millions to stabilize, third-party labs can achieve frontier-level performance at a fraction of the historical cost.
Despite these serious commercial accusations, the legal environment remains remarkably unsettled. Independent forensic audits verifying the scale of these attacks have not been peer-reviewed or submitted to judicial oversight. Furthermore, because raw AI-generated text outputs generally lack copyright eligibility under United States law, aggrieved labs cannot rely on traditional copyright infringement claims. Instead, enforcement is channeled through breach-of-contract lawsuits based on violations of terms of service—a legal mechanism that struggles significantly when applied across international jurisdictions.
Industry Standardization Versus Proprietary Defense
Amid the disputes, model distillation remains an essential, officially sanctioned engineering pillar for the ecosystem. Meta Platforms explicitly designed its Llama 3.1 405-billion-parameter model to serve as an open teacher for the global community. The license accompanying Llama 3.1 explicitly permits developers to use its outputs to train and refine smaller variants, such as the 8B and 70B parameter models, cementing synthetic data generation as a core driver of open-source innovation.
Historically, pioneering open-weights releases like Stanford’s Alpaca and LMSYS’s Vicuna were similarly constructed by prompting larger proprietary models to generate instruction datasets. For most enterprise software vendors, distilling internal models to reduce latency and inference costs is simply good fiscal management.
Broader Implications and Future Outlook
The current crisis exposes a fundamental economic paradox: the better an artificial intelligence model performs, the more effective its outputs are as a training signal for competing systems. Making a model broadly accessible via the cloud inherently exposes its underlying logic to extraction.
As the boundaries between legitimate engineering optimization and intellectual property theft blur, technology firms are racing to implement defensive measures. Major labs—including OpenAI, Anthropic, and Google—have reportedly initiated cross-company intelligence-sharing agreements to track automated harvesting rings. Technical countermeasures are also evolving rapidly, incorporating advanced anomaly detection algorithms, behavioral rate-limiting, and invisible output watermarking designed to trace the lineage of generated text.
Nevertheless, industry analysts warn that no clean technological fix exists. Overly aggressive rate-limiting or restrictive user verification harms legitimate enterprise customers, while watermarking techniques can often be scrubbed through fine-tuning. Until international legal frameworks adapt to the realities of generative synthesis, model distillation will persist as both an indispensable tool for efficient software deployment and a contentious frontier of digital geopolitics.