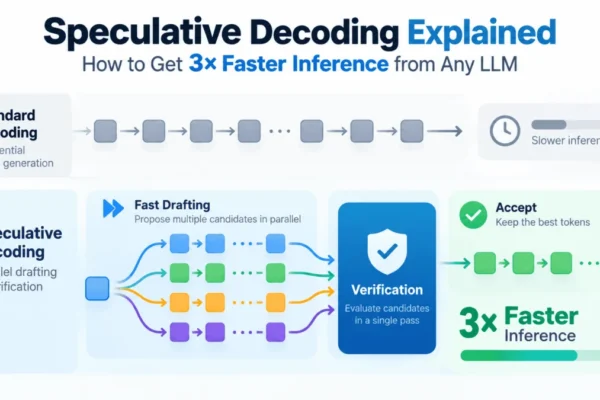
Unlocking Real-Time AI: How Speculative Decoding Delivers 3x Faster LLM Inference Without Sacrificing Quality
The rapid commercial adoption of large language models (LLMs) has collided with a fundamental physical constraint of modern computer hardware:...
