

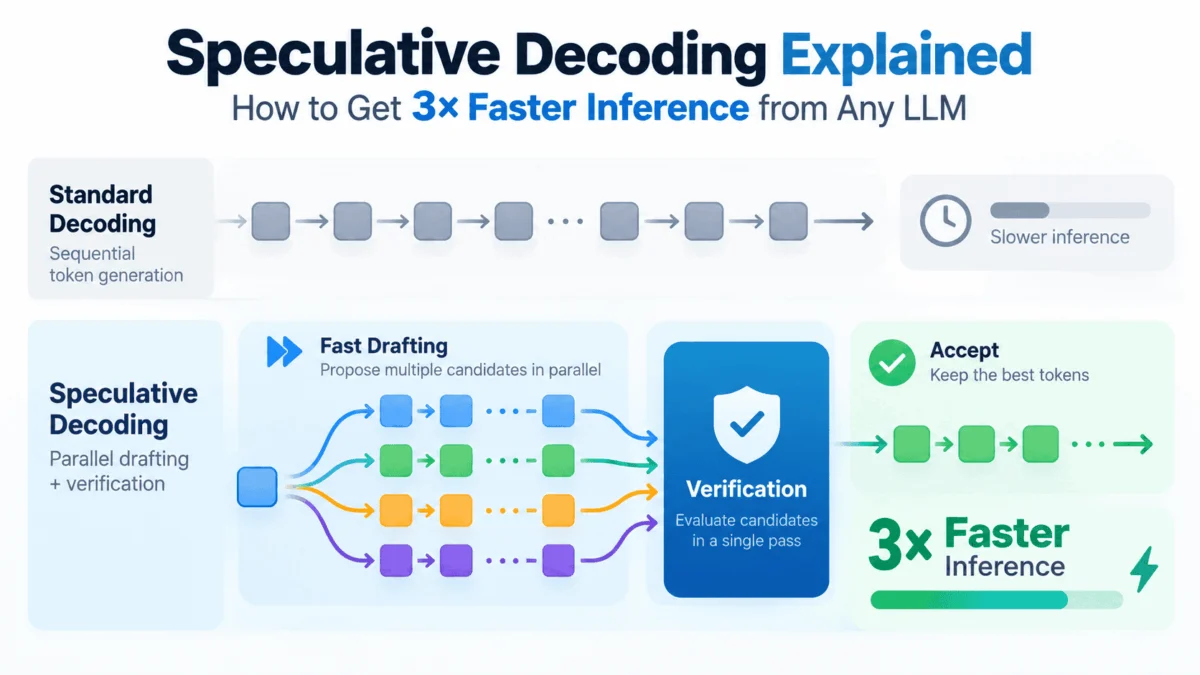
Breaking the Inference Bottleneck: How Speculative Decoding Delivers Up to 3x Faster LLM Generation
The rapid proliferation of generative artificial intelligence across industries has laid bare a fundamental engineering paradox: while modern large language...