In the modern enterprise landscape, the deployment of machine learning models has shifted from an experimental pursuit to a core operational strategy. However, a model that predicts accurately and a model whose reasoning can be explicitly explained are two entirely different achievements, and increasingly, only one remains optional. Consider a standard enterprise churn model that flags a loyal, five-year customer as high-risk. If no one on the technical or business team can articulate the underlying rationale, it ceases to be an interesting data anomaly. Instead, it transforms into an indefensible business decision—indefensible to a department manager, unsettling to the customer, and problematic under emerging regulatory frameworks.
With the implementation of the European Union Artificial Intelligence Act, particularly Article 13, high-risk AI systems must now provide sufficient transparency for deployers to interpret their outputs. This legislative shift has firmly transitioned interpretability from an academic research topic into a mandatory deployment requirement for a growing segment of production systems. To navigate this landscape, data science teams must move beyond legacy metrics and adopt rigorous, mathematically grounded explanation frameworks.
The Evolution of Model Interpretability
Model interpretability measures the degree to which a human can comprehend the cause-and-effect relationship behind a model’s specific output. This definition bifurcates into two distinct analytical domains: global interpretability and local interpretability.
Global interpretability seeks to understand the entire logic of the model, mapping how different features influence predictions across the entire dataset. Conversely, local interpretability zeroes in on a single prediction, answering why the algorithm arrived at a specific conclusion for a specific data point. Historically, data science teams relied on built-in feature importance attributes inherent to ensemble models or coefficients derived from linear regressions. While computationally efficient, these traditional methods present profound limitations. They are strictly global by construction, plagued by biases toward high-cardinality features, and entirely absent when encountering complex architectures like deep neural networks or proprietary black-box application programming interfaces (APIs).
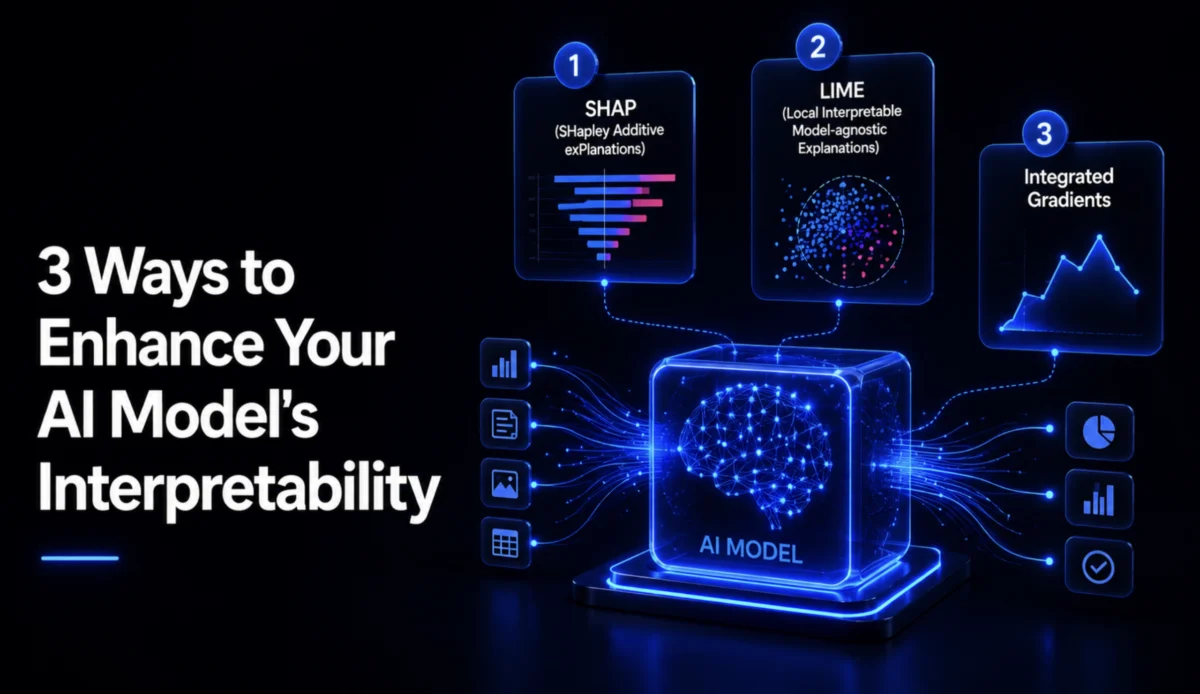
To bridge this gap, modern machine learning workflows employ advanced attribution methodologies. The following sections explore a standardized customer churn scenario to demonstrate how three distinct techniques—SHAP, LIME, and Integrated Gradients—extract explainable insights from complex architectures.
Establishing the Experimental Baseline
To evaluate these interpretability frameworks objectively, a standardized dataset must be utilized where the true underlying drivers of customer churn are known beforehand. By grounding our analysis in a controlled environment, we can verify whether each method yields a plausible explanation rather than a superficial correlation.
Below is the foundational Python script, utilizing standard libraries such as NumPy, Pandas, and Scikit-Learn, which generates a synthetic customer churn dataset and trains a baseline gradient-boosted decision tree classifier.
# churn_data.py
import numpy as np
import pandas as pd
from sklearn.ensemble import GradientBoostingClassifier
from sklearn.model_selection import train_test_split

rng = np.random.default_rng(42)
n = 2000

tenure_months = rng.integers(1, 72, n)
monthly_charge = rng.normal(70, 25, n).clip(15, 200)
support_tickets = rng.poisson(1.5, n)
contract_is_monthly = rng.integers(0, 2, n)  # 1 = month-to-month, 0 = annual+
late_payments = rng.poisson(0.8, n)

# Ground truth logic: short tenure, monthly contracts, and high support tickets increase churn probability
logit = (
    -1.5
    - 0.04 * tenure_months
    + 0.015 * monthly_charge
    + 0.35 * support_tickets
    + 1.1 * contract_is_monthly
    + 0.25 * late_payments
)

prob_churn = 1 / (1 + np.exp(-logit))
churned = (rng.uniform(0, 1, n) < prob_churn).astype(int)

df = pd.DataFrame(
    "tenure_months": tenure_months,
    "monthly_charge": monthly_charge,
    "support_tickets": support_tickets,
    "contract_is_monthly": contract_is_monthly,
    "late_payments": late_payments,
    "churned": churned,
)

FEATURES = ["tenure_months", "monthly_charge", "support_tickets", "contract_is_monthly", "late_payments"]
X = df[FEATURES]
y = df["churned"]

X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)

model = GradientBoostingClassifier(random_state=42)
model.fit(X_train, y_train)

if __name__ == "__main__":
    print(f"Train accuracy: model.score(X_train, y_train):.3f")
    print(f"Test accuracy: model.score(X_test, y_test):.3f")
    print(f"Churn rate in data: y.mean():.1%")
Executing this script yields a test accuracy of approximately 0.698 against a baseline churn rate of 36.8%, representing a moderately skilled model. Throughout the subsequent technical evaluations, the focal point of analysis remains a specific individual profile: X_test.iloc[0], a customer characterized by 53 months of tenure and 5 recent support tickets.
Method 1: SHAP (SHapley Additive exPlanations)
Grounded in cooperative game theory, SHAP treats individual features as players in a cooperative game where the model prediction represents the total payout. By averaging a feature’s marginal contribution across every possible combination of inputs, SHAP computes a mathematically rigorous, consistent attribution value. Released in its iterative production versions, the SHAP library remains a premier choice for enterprise interpretability.
import shap
import numpy as np
import pandas as pd
from churn_data import model, X_test, FEATURES

explainer = shap.TreeExplainer(model)
shap_values = explainer(X_test)

# Global calculation: average absolute contribution per feature
mean_abs = np.abs(shap_values.values).mean(axis=0)
global_importance = pd.Series(mean_abs, index=FEATURES).sort_values(ascending=False)
When applied globally, SHAP often recalculates feature hierarchies differently than standard .feature_importances_ attributes. Locally, when evaluating our target customer who possesses 53 months of tenure but 5 recent support tickets, the output reveals that support tickets contribute +2.81 to the customer’s churn log-odds. This vastly overshadows the protective -0.58 pull exerted by the customer’s long tenure. Consequently, the model registers an 89.5% churn risk probability. While TreeSHAP provides rapid computations for tree-based architectures, its generalized variants demand higher computational overhead.
Method 2: LIME (Local Interpretable Model-agnostic Explanations)
Rather than establishing exact game-theoretic attributions, Local Interpretable Model-agnostic Explanations (LIME) constructs a localized surrogate model. By generating a cloud of perturbed data samples around a specific prediction, weighting them by their distance to the original instance, and fitting an interpretable linear model, LIME approximates complex decision boundaries locally.
import pandas as pd
from lime.lime_tabular import LimeTabularExplainer
from churn_data import model, X_train, X_test, FEATURES

customer = X_test.iloc[0]

explainer = LimeTabularExplainer(
    X_train.values, feature_names=FEATURES,
    class_names=["stayed", "churned"], mode="classification", random_state=42,
)

def predict_proba_df(x):
    return model.predict_proba(pd.DataFrame(x, columns=FEATURES))

explanation = explainer.explain_instance(customer.values, predict_proba_df, num_features=5)
LIME’s analysis of our sample customer aligns closely with the SHAP findings: high support ticket counts dominate the positive churn weight, while tenure metrics push toward retention. LIME excels in computational speed and operational flexibility, making it ideal for real-time inference environments with strict latency constraints. However, its reliance on random sampling can introduce minor stochastic variations between successive execution runs.
Method 3: Integrated Gradients
While SHAP and LIME treat models as black boxes, differentiable architectures—such as deep neural networks—allow for gradient-based attribution. Integrated Gradients calculates the path integral of the gradients of the model’s output with respect to the input features, moving along a straight-line trajectory from a neutral baseline to the actual input vector.
import torch
from captum.attr import IntegratedGradients
from churn_data import X_test, FEATURES

# Assuming `net` is a trained PyTorch model and `customer_normalized` is prepared
net.eval()
input_tensor = torch.tensor(customer_normalized, dtype=torch.float32).unsqueeze(0)
input_tensor.requires_grad_()

baseline = torch.zeros_like(input_tensor)
ig = IntegratedGradients(net)

attributions, delta = ig.attribute(input_tensor, baseline, return_convergence_delta=True, n_steps=200)
Using a convergence delta metric—which verifies that attribution sums match output differences—engineers can validate numerical soundness. In empirical testing, convergence deltas frequently approach zero, verifying that the computed attributions accurately reflect neural network mechanics rather than numerical artifacts.
Strategic Selection and Implementation Guidance
Selecting an interpretability framework requires aligning technical constraints with governance objectives:
- SHAP is optimal for tree-based models where unified global hierarchies and rigorous local explanations are required simultaneously.
- LIME suits high-throughput, low-latency production environments where fast local approximations are necessary across diverse model types.
- Integrated Gradients should be deployed whenever working with differentiable deep learning architectures that expose internal gradients.
Regulatory compliance and operational trust demand that machine learning engineering teams move beyond naive feature importances. By embracing structured attribution methodologies, organizations can successfully unpack complex algorithmic predictions, ensuring transparency for regulators, stakeholders, and end users alike.